SREday is a worldwide series of community events for engineers who build, ship and run modern software systems. Across cities around the world, we bring together people working in reliability, cloud, DevOps, observability and production engineering to share real-world experience, connect with their local community and explore how these disciplines are evolving in the age of AI.
Companies presenting:
Akamai Technologies, Aram Meem, Beewise, Canonical, Cisco, EPAM Systems, Google, Hyland, IN Groupe, Inter Cars S.A., LTIMindtree, Netflix, Novo Nordisk, Quesma, Replika, VictoriaMetrics
Let’s be honest: debugging production at scale is soul-crushing manual labor. At Google, we decided making thousands of SREs act like human search engines in 2026 was a bug, not a feature. Enter the Agentic SRE Extension — a skill-based framework that lives in your terminal and actually knows its way around Kubernetes. In this high-energy deep dive, I’m showing you exactly how we use modular skills and MCP to chain diagnostic tools, analyze metric regressions, and execute safe mitigations (Rollbacks, Throttling) without the "deleted production" anxiety. We’ll dissect the "Outage Investigator" agent's logic loop, see it draft a technical postmortem in seconds, and discuss why we built this as a portable framework whose skills can be easily leveraged by any modern AI harness. You’ll leave with the code to wire up your own Kubernetes stack and let the agent's skills do the heavy lifting while you drink espresso. No fluff, no 101s. Just AI agents, specialized skills, and less toil.... Read more
This presentation provides a high level overview of Incident Management, the practice of responding to an incident in a structured way. It talks about the general incident lifecycle, the Incident Command System framework, and some general how-to tips on applying it.
The talk is aimed at those who are typically on call, or are responsible for resolving a incident when things go wrong. By the end of the presentation, the audience should have a practical understanding of how to manage a incident.... Read more
Every Engineer knows the feeling: your phone pages at 3am, your heart rate spikes before you've even read the alert, and you're debugging a production issue half-asleep. We treat this as normal. It shouldn't be.
This talk is about on-call health. I'll talk about the different shapes on-call can take and why the structure itself can make burnout better or worse. I'll get into the psychological toll, the anxiety of carrying a pager, the burnout that builds quietly over months, and what actually helps: real training, runbooks people trust, and practice before the real incident hits.... Read more
Databases for logs are usually forced to pick a side: build heavy inverted indexes for the ingested logs and pay for them on every write, or ingest raw data cheaply and pay with slow queries later. Is there a better approach? Yes - to make brute-force scanning so selective that most data is never read. This approach is taken by VictoriaLogs. This talk follows a log entry through the VictoriaLogs engine: how it is ingested with no upfront schema, how it lands in an immutable LSM-like compressed column-oriented storage, and how queries run the same structure in reverse, applying a stack of pruning mechanisms based on time, stream labels, and bloom filters so that only the data that can actually match is ever read. Beyond one system's internals, this is a talk about a design stance: when you specialize in one kind of data and know exactly how it is laid out and how it will be consumed, you can be smarter about what you build, sometimes discarding indexes entirely, and avoiding reading most of the data at all. You leave with a concrete set of patterns you can apply to your own storage problems, whether the data is logs or something else entirely.... Read more
Most organizations invest in an observability solution and assume the results will follow. Six months later the tool is deployed, but alert noise is worse than before, nobody outside the platform team logs in, and the number of incidents hasn't changed. The missing piece is never the technology: it's the operating model around it. I lead the team that has helped several hundred large enterprises across EMEA make their observability actually work, and I'll share what the successful implementations did differently: how they structured the team, how they standardized, and how they proved the value to the business. You'll leave with a checklist of what to get right first.... Read more
Your AI agent changed the code, ran a few commands, and declared victory. Can you reconstruct what happened? Keeping agent trajectories gives you a record of the prompts, tool calls, and outputs behind the result. Analysing those records can help you understand failed tasks, find recurring mistakes, improve how your team uses agents, and investigate suspected misuse. If you only start collecting after something goes wrong, the evidence may already be gone.
This talk will explore what you can learn from stored trajectories and why they’re worth keeping even before you know which questions you’ll need to ask. I’ll also share lessons from building Quesma Shipper, our open-source trajectory collector: dealing with scattered session data, changing formats, and transcripts full of secrets. We’ll discuss how to preserve useful records without creating an unnecessary store of sensitive data, and where trajectories alone fall short as evidence.... Read more
WS Control Tower Account Factory for Terraform (AFT) brings the flexibility of Terraform and the GitOps to governed AWS account provisioning. But AFT is a black box and there's no single dashboard to explain pipeline failures.
In this talk, we follow a failure back to its source and ask the real question of the new SRE era: could AWS DevOps Agent actually investigate and trace it home?
The answer reveals something important about AI operations.... Read more
Observability costs tend to grow faster than traffic, and the usual response, renegotiating with the vendor or cutting retention, treats the symptom rather than the cause. The real driver is almost always a small set of design decisions: unbounded label cardinality, logs carrying work that belongs to metrics, and instrumentation added by default rather than by intent. This talk breaks down where the money actually goes in a modern telemetry pipeline, from the moment a signal is emitted to the moment someone queries it, and shows which changes cut cost without cutting visibility. Drawing on patterns common across platform teams, it covers which changes pay off, which turn out not to be worth the effort, and which trade-offs are worth accepting deliberately. It also covers the point at which sampling stops being safe.... Read more
At Inter Cars, our SRE team keeps e-Catalog running — a B2B e-commerce platform serving customers across 20+ European markets. Engineers work on-call shifts 24/7/365, picking up alerts and responding to malfunctions whenever they hit, day or night. This talk is a practical, honest look at what on-call actually feels like: what causes the frustration and stress, and what — if anything — actually helps. Drawing on real experience running a critical B2B platform, we'll dig into whether burnout can really be managed at all, or whether we just get better at living with it.... Read more
A significant shift in the software engineering industry is happening right now. More and more people are using agents in their workflows to write code - either under close supervision or completely autonomously. Pull requests are written, reviewed, and sometimes even merged without any human involvement. New tools and models are released every week, and there's lots of interest in completely autonomous agents such as OpenClaw and Hermes.
As an observability engineer, my main focus is on making sure I know what's going on in my systems. How to observe coding agents? Do traditional observability principles and techniques still matter in this new stochastic paradigm?
In this talk, I will show you how to keep track what your agents are doing and some of the practices that are forming in the industry as we speak - and whether you can use the tools you already have. If you know the basic observability terms, you are the right person to be in the audience.... Read more
Scaling SRE practices from a single team to an entire engineering organization of 20+ teams is rarely just a technical challenge — it is a cultural one.
In this talk, I will share a real-world case study of how we rolled out standardized SLOs, unified observability dashboards, and actionable alerting across dozens of autonomous delivery teams without creating a central bottleneck. I will cover what worked, what didn't, and the hard-earned lessons from fighting alert fatigue, defining meaningful SLOs, and getting teams to truly own the reliability of their services.
Attendees will leave with a practical playbook for driving a reliability-first culture at scale — and a list of pitfalls to avoid along the way.... Read more
16:30
Wrap up
Scan each other's QR codes & head to a nearby pub!
Complex systems require extensive monitoring and observability. Systems as complex as Kubernetes clusters have so many moving parts that sometimes it's a task and a half just to configure their monitoring properly. This talk is a deep dive into cross-account observability for multiple EKS clusters, exploring various implementation options, outline the pros and cons of each approach, and explanation of one of them in close detail. Whether you're an aspiring engineer seeking best-practice advice, a seasoned professional ready to disagree with everything, or a manager looking for ways to optimize costs -- this talk might be just right for you.... Read more
Today's SRE teams have a lot of data coming in, but just having more information doesn't always mean they can improve system reliability. When observability is all about dashboards, alerts, and increasing numbers of signals, engineers may find themselves spending too much time dealing with noise rather than making systems better.
This discussion explores how to move beyond alerts and build an observability strategy designed around action. We'll explore how to link metrics, logs, traces, events, and business context to the real decisions SREs need to make like spotting new issues, understanding how they affect things, speeding up how we handle incidents, and stopping them from happening again. The aim is not to gather more data, but to make observability a real part of how teams work. This helps them find issues quicker, learn more about what's happening, make decisions with confidence, and keep improving how reliable their systems are.... Read more
A golden image gives you a compliant server on the day it is deployed. It does not keep it compliant for the next three years - patches, agent versions, manual changes and ownership all drift on independent clocks, and at fleet scale that stops being a technical problem and becomes an operating-model problem. This talk presents a lifecycle architecture that treats image build, onboarding, desired-state assessment, controlled remediation and centralised patching as a single control loop across hybrid Windows and Linux estates, and shows where the boundary between each layer belongs. I will cover why assessment and remediation need different risk models, why patching is a separate control plane from configuration, and why a machine that has stopped reporting is a bigger problem than a machine reporting non-compliance.... Read more
Do you have a **service mesh** running in your cluster, or are you considering **Istio** and wondering whether the benefits justify another layer of complexity? As **AI** speeds up prototyping and application changes, **SREs** have more to do than ever.
Let's examine where a **service mesh helps**, and when it simply gives you **more infrastructure to maintain**.
We’ll look **under the hood**, then explore how its **observability capabilities** help you understand **service dependencies** and **troubleshoot traffic**, including calls leaving your cluster.
We’ll also examine where **Istio fits into rapid experimentation**: **A/B testing**, **blue-green deployments**, **shadow traffic**, and recovering when a new component misbehaves.
If you wonder **what a service mesh is**, or if you are simply **lost with your cluster traffic**, this session is for you!... Read more
AI has made engineering teams genuinely faster - but the bill is coming, and it will be paid in more than money. This talk looks at what happens when AI budgets get cut in half: workflows with AI stitched into their spine, engineers who have never debugged without an assistant, and codebases full of generated code that no one truly owns. Skill atrophy is technical debt stored in people, and it has no refactoring. Finally, we'll cover how platform teams can build AI as a detachable dependency rather than a foundation - including one concrete practice you can take back to your team.... Read more
When I joined a team of 8 developers, their Linode Kubernetes Engine infrastructure was built through UI clicks, manual helm deployments, and YAML manifests scattered across environments - and I didn't understand what their application actually did.... Read more
Running observability for devices in the field is a different problem from running it for services on your PaaS. Power, bandwidth and update cadence are fixed by physics, and each one rules out tooling that would be the obvious pick anywhere else. This talk works through the decisions an IoT fleet forces on you: what to collect, where to process it when every byte is metered, how to index without labels, and why storage architecture—not query speed—determines your long-term costs.... Read more
Replacing or refactoring a legacy system while it handles live high-throughput traffic is akin to replacing an airplane engine in mid-flight. In high-load environments where even minutes of downtime result in direct revenue loss, full rewrites are often too risky, making incremental refactoring the only viable path. I will provide real-world engineering strategies for safely modernizing legacy monolithic services under active load without breaching SLAs or risking data integrity. I am going to cover practical execution patterns: isolating legacy boundaries, leveraging the Strangler Fig pattern, deploying feature flags, and executing shadow reads and dual-writes for data storage migrations. Special emphasis is placed on observability and SRE guardrails — how to structure telemetry, automated circuit breakers, and canary deployments to catch performance regressions instantly during transition phases. The audience will gain hard-earned insights into balancing architectural evolution, system stability, and continuous delivery.... Read more
SRE is about making systems reliable, but our efforts to improve reliability can sometimes introduce complexity of their own. This talk explores common SRE traps, including alert fatigue, over-automation, excessive tooling, overengineering, and reliance on “hero” engineers. Through practical examples and real-world lessons, we’ll examine how these challenges can affect the reliability and operability of our systems and how to build systems that are not only reliable, but also maintainable, understandable, and easier to operate.... Read more
16:00
Wrap up
Scan each other's QR codes & head to a nearby pub!
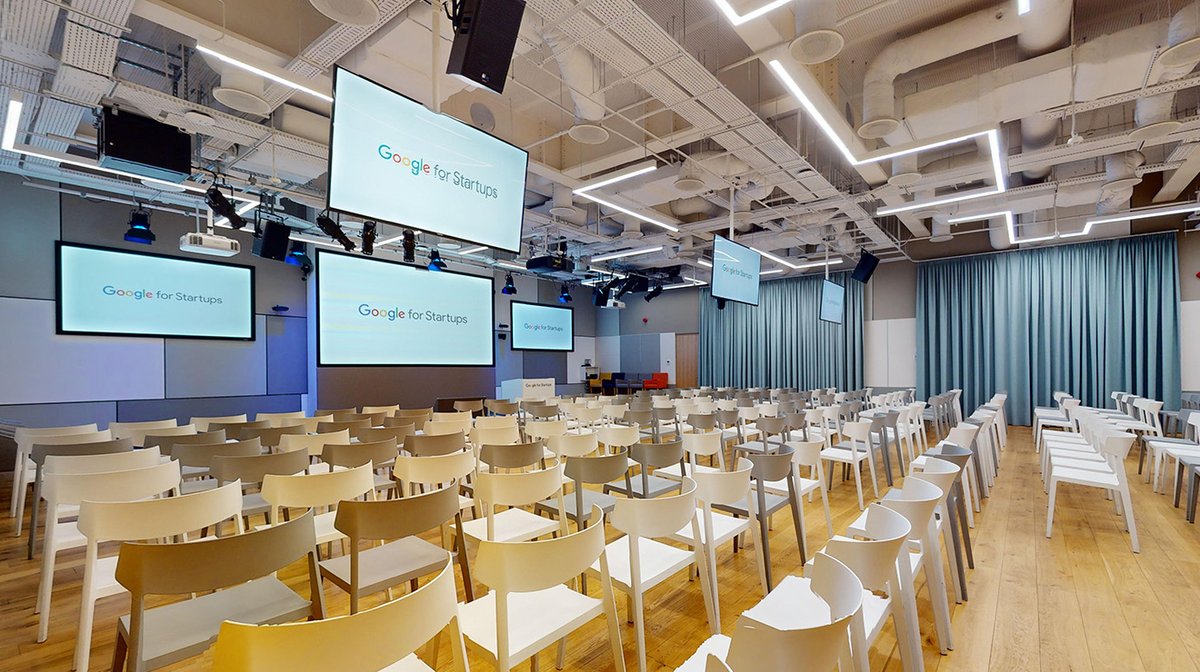
Centrum Praskie Koneser, Plac Konesera 10
03-736 Warsaw, Poland
Sponsors & Partners
Want to become a sponsor? Get in touch!
Joshua Borkowski-Clark
Google
Incident Management at Google
Abstract
This presentation provides a high level overview of Incident Management, the practice of responding to an incident in a structured way. It talks about the general incident lifecycle, the Incident Command System framework, and some general how-to tips on applying it.
The talk is aimed at those who are typically on call, or are responsible for resolving a incident when things go wrong. By the end of the presentation, the audience should have a practical understanding of how to manage a incident.
Bio
Joshua (he/him, they/them) is a Senior Site Reliability Engineer at Google, supporting GCP's Key and Secret Management products. They have extensive experience with internal tooling and cluster-scoped infrastructure, both as a software engineer and an SRE. Joshua contributes to Google-wide resiliency as an Incident Management trainer and volunteer in Google's major incident response team. They graduated from the University of Oxford with a Masters in Computer Science.
Yernar Kenzhetayev
Netflix
On-call health: The Human Side of Reliability
Abstract
Every Engineer knows the feeling: your phone pages at 3am, your heart rate spikes before you've even read the alert, and you're debugging a production issue half-asleep. We treat this as normal. It shouldn't be.
This talk is about on-call health. I'll talk about the different shapes on-call can take and why the structure itself can make burnout better or worse. I'll get into the psychological toll, the anxiety of carrying a pager, the burnout that builds quietly over months, and what actually helps: real training, runbooks people trust, and practice before the real incident hits.
Bio
Yernar is a Reliability Engineer at Netflix with 5+ years of experience across DevOps, infrastructure, and reliability engineering. He works on operational resilience and incident response for large-scale production systems. His work spans SLO operationalization, incident analytics, and reducing toil for engineers with a focus on turning operational pain points into measurable, systemic improvements.
Aliaksandr Valialkin
VictoriaMetrics
How to Create a Database Optimized for Petabytes of Logs and Wide Events
Abstract
Databases for logs are usually forced to pick a side: build heavy inverted indexes for the ingested logs and pay for them on every write, or ingest raw data cheaply and pay with slow queries later. Is there a better approach? Yes - to make brute-force scanning so selective that most data is never read. This approach is taken by VictoriaLogs. This talk follows a log entry through the VictoriaLogs engine: how it is ingested with no upfront schema, how it lands in an immutable LSM-like compressed column-oriented storage, and how queries run the same structure in reverse, applying a stack of pruning mechanisms based on time, stream labels, and bloom filters so that only the data that can actually match is ever read. Beyond one system's internals, this is a talk about a design stance: when you specialize in one kind of data and know exactly how it is laid out and how it will be consumed, you can be smarter about what you build, sometimes discarding indexes entirely, and avoiding reading most of the data at all. You leave with a concrete set of patterns you can apply to your own storage problems, whether the data is logs or something else entirely.
Bio
Aliaksandr is a co-founder and the principal architect of VictoriaMetrics. He is also a well-known author of the popular performance-oriented libraries: fasthttp, fastcache and quicktemplate. Prior to VictoriaMetrics, Aliaksandr held CTO and Architect roles with adtech companies serving high volumes of traffic. He holds a Master’s Degree in Computer Software Engineering. He decided to found VictoriaMetrics after experiencing the shortcomings of all available time series databases and monitoring solutions.
Kuba Rachwalski
Cisco
Observability Isn't a Tool Problem. It's an Org Problem.
Abstract
Most organizations invest in an observability solution and assume the results will follow. Six months later the tool is deployed, but alert noise is worse than before, nobody outside the platform team logs in, and the number of incidents hasn't changed. The missing piece is never the technology: it's the operating model around it. I lead the team that has helped several hundred large enterprises across EMEA make their observability actually work, and I'll share what the successful implementations did differently: how they structured the team, how they standardized, and how they proved the value to the business. You'll leave with a checklist of what to get right first.
Bio
Kuba Rachwalski is Head of EMEA Observability and AIOps Delivery at Cisco. Previously Director of EMEA Professional Services at AppDynamics, with seven years helping companies put observability to work at scale. Based in Kraków.
Przemyslaw Hejman
Quesma
The Agent Did What!? A Flight Recorder for AI Agents
Abstract
Your AI agent changed the code, ran a few commands, and declared victory. Can you reconstruct what happened? Keeping agent trajectories gives you a record of the prompts, tool calls, and outputs behind the result. Analysing those records can help you understand failed tasks, find recurring mistakes, improve how your team uses agents, and investigate suspected misuse. If you only start collecting after something goes wrong, the evidence may already be gone.
This talk will explore what you can learn from stored trajectories and why they’re worth keeping even before you know which questions you’ll need to ask. I’ll also share lessons from building Quesma Shipper, our open-source trajectory collector: dealing with scattered session data, changing formats, and transcripts full of secrets. We’ll discuss how to preserve useful records without creating an unnecessary store of sensitive data, and where trajectories alone fall short as evidence.
Bio
Seasoned software engineer and architect with 15 years of industry experience and a strong background in systems design and operations. Currently a member of the founding team at Quesma, building tools that help engineering teams
understand how AI coding agents work, what they cost, and the value they deliver. Previously helped build Elastic’s Cloud offering and delivered crowd testing and mobile app quality tooling at scale at uTest/Applause.
Ali Ogun
Hyland
Mission (A)Impossible: AWS DevOps Agent Meets AFT
Abstract
WS Control Tower Account Factory for Terraform (AFT) brings the flexibility of Terraform and the GitOps to governed AWS account provisioning. But AFT is a black box and there's no single dashboard to explain pipeline failures.
In this talk, we follow a failure back to its source and ask the real question of the new SRE era: could AWS DevOps Agent actually investigate and trace it home?
The answer reveals something important about AI operations.
Bio
Ali Ogun is a Cloud Engineer at Hyland and 5x AWS Community Builder with 9+ years of experience transforming AWS ecosystems into scalable, enterprise-ready platforms. Combining a background in software development with aviation-grade discipline from elite pilot selection programs, Ali specializes in Platform Engineering, IaC, and CI/CD governance. His work in cloud self-service automation has dramatically streamlined enterprise developer workflows, and his technical writing reaches over 200,000 engineers globally.
Hanna Novikava
SRE/DevOps Engineer
Your Observability Bill Is a Design Problem, Not a Vendor Problem
Abstract
Observability costs tend to grow faster than traffic, and the usual response, renegotiating with the vendor or cutting retention, treats the symptom rather than the cause. The real driver is almost always a small set of design decisions: unbounded label cardinality, logs carrying work that belongs to metrics, and instrumentation added by default rather than by intent. This talk breaks down where the money actually goes in a modern telemetry pipeline, from the moment a signal is emitted to the moment someone queries it, and shows which changes cut cost without cutting visibility. Drawing on patterns common across platform teams, it covers which changes pay off, which turn out not to be worth the effort, and which trade-offs are worth accepting deliberately. It also covers the point at which sampling stops being safe.
Bio
Hanna Novikava is a Site Reliability / DevOps Engineer working on infrastructure, delivery and observability for financial platforms and beyond. Her work focuses on Kubernetes, infrastructure as code, and keeping platform teams effective as systems and their operating costs grow. She believes CI should stand for continuous improvement as much as continuous integration - pipelines are only worth as much as the practices around them. Based in Warsaw.
Piotr Wojcikowski
Inter Cars S.A.
"Response Code: Burnout" — How to Survive On-Call in SRE
Abstract
At Inter Cars, our SRE team keeps e-Catalog running — a B2B e-commerce platform serving customers across 20+ European markets. Engineers work on-call shifts 24/7/365, picking up alerts and responding to malfunctions whenever they hit, day or night. This talk is a practical, honest look at what on-call actually feels like: what causes the frustration and stress, and what — if anything — actually helps. Drawing on real experience running a critical B2B platform, we'll dig into whether burnout can really be managed at all, or whether we just get better at living with it.
Bio
Piotr Wojcikowski is a Support Engineer in Site Reliability Engineering at Inter Cars S.A. With over a decade at the company, he's worked across different departments of the organization, giving him a strong understanding of the business context behind the systems he now supports. Day to day, he uses Grafana, Kibana, and ITSM tools to detect and resolve incidents — bringing both technical monitoring and organizational insight to the on-call rotation.
Mateusz Kulewicz
Canonical
Observing Coding Agents
Abstract
A significant shift in the software engineering industry is happening right now. More and more people are using agents in their workflows to write code - either under close supervision or completely autonomously. Pull requests are written, reviewed, and sometimes even merged without any human involvement. New tools and models are released every week, and there's lots of interest in completely autonomous agents such as OpenClaw and Hermes.
As an observability engineer, my main focus is on making sure I know what's going on in my systems. How to observe coding agents? Do traditional observability principles and techniques still matter in this new stochastic paradigm?
In this talk, I will show you how to keep track what your agents are doing and some of the practices that are forming in the industry as we speak - and whether you can use the tools you already have. If you know the basic observability terms, you are the right person to be in the audience.
Bio
Mateusz Kulewicz, Canonical
An observability-focused software engineer with a tendency to dive into new hobbies related to travel or maps every few months. At Canonical, Mateusz writes and maintains charms that are part of the Canonical Observability Stack. Outside of work, he finds the most joy in traveling or practising one of the many languages he has attempted to learn.
Ilia Matytcin
EPAM Systems
SRE at Scale: How We Standardized Reliability Across 20+ Teams
Abstract
Scaling SRE practices from a single team to an entire engineering organization of 20+ teams is rarely just a technical challenge — it is a cultural one.
In this talk, I will share a real-world case study of how we rolled out standardized SLOs, unified observability dashboards, and actionable alerting across dozens of autonomous delivery teams without creating a central bottleneck. I will cover what worked, what didn't, and the hard-earned lessons from fighting alert fatigue, defining meaningful SLOs, and getting teams to truly own the reliability of their services.
Attendees will leave with a practical playbook for driving a reliability-first culture at scale — and a list of pitfalls to avoid along the way.
Bio
Ilia Matytcin is a Senior Site Reliability Engineer with over 6 years of experience designing and operating resilient Azure- and AWS-native systems. He specializes in Kubernetes hardening, Infrastructure-as-Code (Terraform, Pulumi), and observability (Datadog, Prometheus, OpenTelemetry), and has led SRE and observability adoption across multiple delivery teams — improving availability to 99.95% and cutting MTTR by up to 40%.
Ilia is a Microsoft Certified Azure DevOps Engineer Expert (AZ-400) and HashiCorp Certified Terraform Associate, with a strong background in SLO design, incident response, and on-call operations. Outside of work, he enjoys travelling and exploring how AI can enhance engineering workflows.
Kirill Solovei
Replika
Centralized cross-account EKS observability
Abstract
Complex systems require extensive monitoring and observability. Systems as complex as Kubernetes clusters have so many moving parts that sometimes it's a task and a half just to configure their monitoring properly. This talk is a deep dive into cross-account observability for multiple EKS clusters, exploring various implementation options, outline the pros and cons of each approach, and explanation of one of them in close detail. Whether you're an aspiring engineer seeking best-practice advice, a seasoned professional ready to disagree with everything, or a manager looking for ways to optimize costs -- this talk might be just right for you.
Bio
Dedicated and hardworking individual with over 10 years of experience and strong focus on Linux system engineering, security and automation.
Mary Adeseluka
LTIMindtree
Beyond Alerts: Building an Observability Strategy That Drives SRE Action
Abstract
Today's SRE teams have a lot of data coming in, but just having more information doesn't always mean they can improve system reliability. When observability is all about dashboards, alerts, and increasing numbers of signals, engineers may find themselves spending too much time dealing with noise rather than making systems better.
This discussion explores how to move beyond alerts and build an observability strategy designed around action. We'll explore how to link metrics, logs, traces, events, and business context to the real decisions SREs need to make like spotting new issues, understanding how they affect things, speeding up how we handle incidents, and stopping them from happening again. The aim is not to gather more data, but to make observability a real part of how teams work. This helps them find issues quicker, learn more about what's happening, make decisions with confidence, and keep improving how reliable their systems are.
Bio
Mary Adeseluks is a Cloud Engineer passionate about building reliable, scalable, and observable systems in the cloud. I specialize in cloud infrastructure, SRE, automation, and observability, helping engineering teams manage complex systems with greater reliability and confidence. I enjoy turning operational challenges into practical engineering solutions from improving reliability and incident response to designing infrastructure and observability practices that enable teams to move faster without compromising stability.
Michal Gawron
Novo Nordisk
Beyond the Golden Image: Continuous Compliance for a Hybrid Server Fleet
Abstract
A golden image gives you a compliant server on the day it is deployed. It does not keep it compliant for the next three years - patches, agent versions, manual changes and ownership all drift on independent clocks, and at fleet scale that stops being a technical problem and becomes an operating-model problem. This talk presents a lifecycle architecture that treats image build, onboarding, desired-state assessment, controlled remediation and centralised patching as a single control loop across hybrid Windows and Linux estates, and shows where the boundary between each layer belongs. I will cover why assessment and remediation need different risk models, why patching is a separate control plane from configuration, and why a machine that has stopped reporting is a bigger problem than a machine reporting non-compliance.
Bio
Michal Gawron is a technical lead working on cloud and server platform automation for large regulated enterprises. He designs lifecycle tooling for hybrid Windows and Linux estates - golden images, desired-state compliance, remediation automation and centralised patching - with a focus on turning complex infrastructure processes into repeatable platform capabilities. He is based in Warsaw.
Marek Smigielski
IN Groupe
Is Istio Service Mesh Still Worth the Money in the AI Era?
Abstract
Do you have a service mesh running in your cluster, or are you considering Istio and wondering whether the benefits justify another layer of complexity? As AI speeds up prototyping and application changes, SREs have more to do than ever.
Let's examine where a service mesh helps, and when it simply gives you more infrastructure to maintain.
We’ll look under the hood, then explore how its observability capabilities help you understand service dependencies and troubleshoot traffic, including calls leaving your cluster.
We’ll also examine where Istio fits into rapid experimentation: A/B testing, blue-green deployments, shadow traffic, and recovering when a new component misbehaves.
If you wonder what a service mesh is, or if you are simply lost with your cluster traffic, this session is for you!
Bio
Marek Śmigielski is a System Architect at IN Groupe. His almost 25-year career spans various IT roles—from software development and production support to product management—giving him a broad perspective on building and operating software. With an SRE (Site Reliability Engineering) mindset, Marek brings the realities of running production software into architectural decisions. He focuses on making complex systems easier to understand and maintain.
Hubert Poznanski
Senior DevOps Engineer
Faster, Smarter, Fragile: The human cost of AI Boom
Abstract
AI has made engineering teams genuinely faster - but the bill is coming, and it will be paid in more than money. This talk looks at what happens when AI budgets get cut in half: workflows with AI stitched into their spine, engineers who have never debugged without an assistant, and codebases full of generated code that no one truly owns. Skill atrophy is technical debt stored in people, and it has no refactoring. Finally, we'll cover how platform teams can build AI as a detachable dependency rather than a foundation - including one concrete practice you can take back to your team.
Bio
DevOps Engineer with over a decade of experience operating large-scale cloud infrastructure, including Kubernetes, petabyte-scale storage, and distributed databases. His work focuses on platform engineering, automation, and the practical adoption of AI in infrastructure operations.
Artur Polek
Akamai Technologies
The Black Box Strategy: Building SRE Infrastructure for Unknown Applications
Abstract
When I joined a team of 8 developers, their Linode Kubernetes Engine infrastructure was built through UI clicks, manual helm deployments, and YAML manifests scattered across environments - and I didn't understand what their application actually did.
Bio
Artur Polek is a Senior Site Reliability Engineer at Akamai Technologies with over 7 years of experience in SRE and DevOps across enterprise-scale systems. He spent nearly 4 years managing AppDynamics cSaaS reliability and operations at Cisco, building resilient infrastructure for complex distributed applications. Artur specializes in Kubernetes infrastructure automation, observability stack architecture, and platform reliability—often building resilient systems for applications he doesn't fully understand. Holding both CKA and CKAD certifications alongside a Master's in ICT from Cracow University of Technology, his approach combines container orchestration expertise with modern SRE practices. Based in Kraków, Poland, he brings a unique perspective shaped by his former role as a Polish Football Association referee, where split-second decision-making under pressure continues to inform his incident response approach.
Oleksandr Zhyhalo
Beewise
Observability for IoT Fleets Without Going Bankrupt
Abstract
Running observability for devices in the field is a different problem from running it for services on your PaaS. Power, bandwidth and update cadence are fixed by physics, and each one rules out tooling that would be the obvious pick anywhere else. This talk works through the decisions an IoT fleet forces on you: what to collect, where to process it when every byte is metered, how to index without labels, and why storage architecture—not query speed—determines your long-term costs.
Bio
Oleksandr Zhyhalo is a Senior DevOps Engineer at Beewise, where he owns the AWS infrastructure behind a fleet of 2,000 solar-powered robotic beehives — from architecture and security through to the provisioning, update and telemetry pipelines that keep the fleet running.
Alex Dainiak
Aram Meem
Incremental Refactoring of Legacy Systems Under Load
Abstract
Replacing or refactoring a legacy system while it handles live high-throughput traffic is akin to replacing an airplane engine in mid-flight. In high-load environments where even minutes of downtime result in direct revenue loss, full rewrites are often too risky, making incremental refactoring the only viable path. I will provide real-world engineering strategies for safely modernizing legacy monolithic services under active load without breaching SLAs or risking data integrity. I am going to cover practical execution patterns: isolating legacy boundaries, leveraging the Strangler Fig pattern, deploying feature flags, and executing shadow reads and dual-writes for data storage migrations. Special emphasis is placed on observability and SRE guardrails — how to structure telemetry, automated circuit breakers, and canary deployments to catch performance regressions instantly during transition phases. The audience will gain hard-earned insights into balancing architectural evolution, system stability, and continuous delivery.
Bio
Technical Lead with extensive hands-on experience across backend development (Java, Go, Python), mobile, web, and DevOps practices. Working at the intersection of architecture, reliability, and team leadership, Aliaksandr specializes in building scalable marketplace platforms and leading complex engineering initiatives through uncertainty. Alongside his engineering leadership roles, he is an active founder developing AI-driven startup products.
Felix Masomera
Site Reliability Engineer
When Reliability Becomes the Problem: The SRE Traps Nobody Talks About
Abstract
SRE is about making systems reliable, but our efforts to improve reliability can sometimes introduce complexity of their own. This talk explores common SRE traps, including alert fatigue, over-automation, excessive tooling, overengineering, and reliance on “hero” engineers. Through practical examples and real-world lessons, we’ll examine how these challenges can affect the reliability and operability of our systems and how to build systems that are not only reliable, but also maintainable, understandable, and easier to operate.
Bio
I am a Site Reliability Engineer with seven years of experience spanning software engineering, IoT, cloud infrastructure, and automation. I currently work as an SRE at Bentley Systems. My technical experience includes Kubernetes, Terraform, Ansible, Jenkins, cloud platforms including AWS, GCP, and Azure, Python, Java, and observability.
Let’s be honest: debugging production at scale is soul-crushing manual labor. At Google, we decided making thousands of SREs act like human search engines in 2026 was a bug, not a feature. Enter the Agentic SRE Extension — a skill-based framework that lives in your terminal and actually knows its way around Kubernetes. In this high-energy deep dive, I’m showing you exactly how we use modular skills and MCP to chain diagnostic tools, analyze metric regressions, and execute safe mitigations (Rollbacks, Throttling) without the "deleted production" anxiety. We’ll dissect the "Outage Investigator" agent's logic loop, see it draft a technical postmortem in seconds, and discuss why we built this as a portable framework whose skills can be easily leveraged by any modern AI harness. You’ll leave with the code to wire up your own Kubernetes stack and let the agent's skills do the heavy lifting while you drink espresso. No fluff, no 101s. Just AI agents, specialized skills, and less toil.
Bio
Riccardo loves caipirinhas and 🍷 Amarone, playing 🎹 piano and 🏊🏻🚴🏿🏃♀️ triathlons; he's been passionate about Mathematics since he was 4. He's still in love with Ruby and Rails. Former network administrator, sysadmin, and Ruby on Rails developer, Riccardo has been in operations for 20+ years and still likes to spend time coding (better if Ruby). He loves engaging with customers and help them run their operations reliably and successfully in the cloud. He co-authored the SRE Extension. More: https://g.dev/ricc