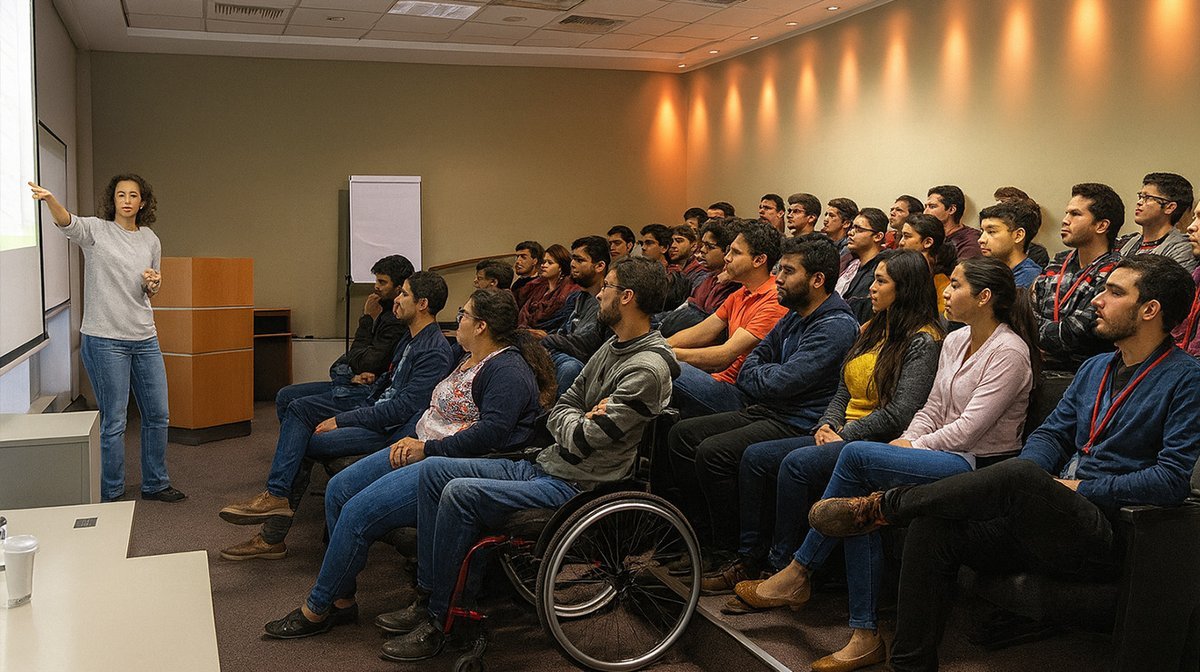
SREday is a worldwide series of community events for engineers who build, ship and run modern software systems. Across cities around the world, we bring together people working in reliability, cloud, DevOps, observability and production engineering to share real-world experience, connect with their local community and explore how these disciplines are evolving in the age of AI.
Rodovia Jornalista Francisco Aguirre Proença
SP101, Km 09 - S/N - Chácaras Assay, Hortolândia - SP, 13186-900, Brazil
Minors are not allowed to attend or participate in this event.
Sponsors & Partners
Want to become a sponsor? Get in touch!
Joanne Rodrigues
Edwards Lifesciences
Observability in Complex Environments
Abstract
Explore the journey of building observability across complex, multi-platform environments. Learn how to overcome data silos, connect the dots across your technology landscape, and advance your observability practice.
Bio
Joanne Rodrigues is a Senior Observability Architect with extensive experience helping large organizations build and evolve their monitoring and observability practices. She developed her own Tool Consolidation Roadmap, a strategy designed to help companies simplify their monitoring landscape and reduce tool overhead. She shares this approach with organizations worldwide, helping them navigate the journey from fragmented monitoring to mature, scalable observability.
Igor Muralhes
ZenerIM
Beyond Software: Applying SRE to Industrial Critical Systems
Abstract
SRE is typically associated with cloud platforms and software services, but many of its core principles can be applied to industrial operations as well.
Through practical examples from connected industrial automation systems, this talk shows how observability, incident management, root cause analysis, and reliability engineering help maintain critical physical assets. The session offers a unique perspective on how SRE practices can bridge the gap between software and the real world.
Bio
As a Technical Support Engineer at Ecolab, I support connected industrial systems across Latin America, specializing in industrial IoT, automation, instrumentation, and remote diagnostics. My work involves troubleshooting critical operations, investigating incidents, and improving the reliability of industrial assets. I am particularly interested in the intersection between reliability engineering, industrial operations, and modern monitoring practices.
Rod Anami
Staff Site Reliability Engineer
Can I hire AI agents to do my SRE work?
Abstract
Building a DOE-Architected Copilot CLI Harness for Multi-Month ITSM Analysis When production fails, we jump into our terminals. But to prevent the next failure, we need to analyze months of historical context trapped inside enterprise ITSM platforms like ServiceNow and BMC Helix. Throwing 6 months of noisy ticket data directly into an LLM context window is a recipe for high cloud bills, hallucinated patterns, and "context anxiety". In this talk, you'll learn how to build a local, highly disciplined SRE Agent Harness using GitHub Copilot CLI integrated with a DOE (Directive, Orchestration, Execution) architecture. We will detail the exact data engineering pipelines required to extract, parse, and enrich months of ITSM records into clean, semantic timelines before feeding them to your agent.
Bio
Rod Anami is a Staff Site Reliability Engineer and author specializing in global cloud infrastructure, data-driven observability, and Agentic AI. As the Lead SRE at Kyndryl’s Center of Excellence, he orchestrates enterprise-scale modernization for a global client base while leading an SRE Guild spanning 40+ countries. Rod serves as the Global SRE Profession Leader, having architected the technical accreditation and enablement programs for thousands of engineers. Rod was the first-place winner of the 2025 Kyndryl AI Hackathon and has extensively experimented with Agentic AI, including the development of custom MCP (Model Context Protocol) servers to bridge LLMs with enterprise data. His expertise extends to Data Engineering, where he designs ETL pipelines and conducts exploratory data analysis on platforms like ServiceNow and CRM to drive proactive reliability. Rod is a recognized thought leader, the curator of the SRE Manifesto, and co-author of the book "Becoming a Rockstar SRE". He bridges the gap between high-level technical strategy and hands-on engineering excellence.
Leonardo Camara & Pedro Alex da Costa & Henrique C
Banco Bradesco
1 Além do RCA: Evoluindo para uma cultura de blameless PostMortem
Abstract
1 Além do RCA: Evoluindo para uma cultura de blameless PostMortem A ideia é mostrar a metodologia de postmortem colaborativo que fazemos no bradesco, indo muito além do RCA padrao, com analise de causas raizes, metodologias de análise (5pqs, FTA, Barreira de falhas e Ishikawa) eventos contribuintes, planos de melhoria, soluções de contorno, definitivas E os modelos de trabalho em gestão de problemas (Centralizado vs descentralizado na cultura SRE/Devops de build'n'run.
Bio
Leonardo Camara is a Technology Manager with 15 years of experience in SRE, Problem Management, and ITSM across major organizations such as Itaú, Vivo, Banco Pan, and Banco Bradesco. He specializes in building resilient systems, reducing systemic failures, and establishing Emergency Response Teams (ERTs) in critical, high-scale environments. Pedro Alex da Costa is an SRE Specialist at Bradesco with over two decades of experience in technology and operations, including key Site Reliability Engineering roles at Vivo (Telefônica Brasil). Based in São Paulo, Brazil, Pedro specializes in system resilience, root-cause failure analysis, observability, and post-mortem execution to ensure high availability across complex enterprise systems. Henrique C. is a IT Operations Manager & SRE Lead with over 25 years in technology, Henrique manages SRE and incident management for mission-critical operations at Bradesco Command Center. He specializes in business continuity, service recovery, ModernOps, automation, and AIOps to build resilient, high-availability IT systems.
Joao Hugo Ferreira
ECI Software Solutions
Are Seniors Still Necessary?
Abstract
Why the rise of AI makes deep engineering experience more valuable than ever – not less.
Bio
Senior DevOps & Platform Engineer with 8+ years of experience building and running cloud-native infrastructure on Azure and AWS.
Leandro Fachinelli
IBM
From Copilot to Autopilot: When Should an SRE Let AI Touch Production
Abstract
AI is starting to move beyond helping SREs investigate incidents and into actually taking action. That raises an important question: when is it safe to let an AI agent change something in production?
This talk explores that transition from AI copilots to more autonomous SRE agents. We’ll look at practical ways to control that autonomy, including human approval, least privilege, policy enforcement, blast radius, dry runs, rollback, observability, and continuous evaluation.
Using real-world incident scenarios, I’ll show where AI can add value today, where it should still stop and ask for help, and what needs to be in place before we let it act on its own.
The goal is not to replace SREs. It is to reduce repetitive operational work while keeping production safe, observable, and under control.
Bio
Senior Site Reliability and Observability Engineer with extensive experience in enterprise infrastructure, cloud technologies, monitoring, automation, and reliability engineering. Specialized in observability platforms such as Instana, Dynatrace, Splunk among others, and in building scalable solutions that improve operational efficiency, visibility, and system resilience. Passionate about automation, infrastructure architecture, and the practical application of AI to solve complex technical challenges.
Thiago Rodrigues Silva
Bosch Digital
From Prompt to Production: Speeding Up AI Agents Deployment on Google Cloud with Natural Language Using Gemini CLI
Abstract
How to Integrate Agent Development Kit (ADK), Cloud Run, and Gemini Enterprise into a Prompt-Driven DevOps Pipeline to Replace Complex Scripts with Natural Language, Along with IAM Security and Governance.
The era of artificial intelligence agents has presented a new challenge for SRE, Platform Engineering and DevOps teams: how can they quickly deploy, version, and scale agent-based systems without compromising infrastructure security?
In this 25-minute session, we’ll present how to build an intelligent harness capable of translating natural language intentions directly into the Gemini CLI to orchestrate the full deployment lifecycle of agents and custom skills. Let's dive in the operational side of deploying and running AI agents and focus on infrastructure, reliability, automation, observability, deployment workflows, and reducing operational toil.
What you’ll learn in this session:
Architecture & Security: How to implement the principle of least privilege by separating Deployment Service Accounts (Deployer SA) from Runtime Service Accounts (Runtime SA), and Agent Platform Identity (Platform ID SA) on Google Cloud Platform.
Agent Development: Modular development of agents and tools in Python using the Google Agent Development Kit (ADK) and google-agents-cli.
Deployment and Operational Side: Container packaging and deployment on Google Cloud Run and the Gemini Enterprise Agent Platform. Infrastructure, reliability, automation, observability, deployment workflows, and reducing operational toil.
Natural Language Harness: How to create system instructions to transform the Gemini CLI into a secure, autonomous, and deterministic DevOps operator.
Bio
With over 26 years of IT experience, I am a Senior DevOps Engineer at Bosch Digital, where I provide consulting and support for cloud computing services using leading providers such as Azure, AWS, GCP, and OCI. I also have experience with infrastructure as code (IaC), automation, containerization, orchestration, and observability, using tools such as Terraform, Ansible, Docker, Kubernetes, and Observability (Prometheus + Grafana / LGTM stack + New Relic).
Former Sr. Multicloud Architect focused on Google Cloud solutions. Coordinator, Speaker, Mentor and Panelist at TDC Floripa, TDC São Paulo and Devopsdays Campinas 2025 and 2026.
Alexandre Monteiro
Itau Unibanco
From Automation to Agentic Operations: The Next Frontier of SRE
Abstract
Modern SRE practices have evolved from manual operations to highly automated platforms, with Infrastructure as Code, CI/CD, observability, and automated incident response becoming standard components of reliable systems.
The next evolution is the introduction of AI agents into operational workflows.
This talk explores the transition from deterministic automation to Agentic Operations, where AI-powered agents can analyze telemetry, correlate events, assist with incident investigation, recommend remediation actions, and potentially execute operational tasks under well-defined guardrails.
We will discuss the opportunities and challenges of bringing agentic AI into SRE environments, including observability, incident management, human-in-the-loop workflows, security, permissions, reliability, and the risks of autonomous actions.
The session will focus on practical architecture patterns and real-world operational scenarios, showing how SRE teams can gradually introduce AI agents without losing control, auditability, or reliability.
The goal is not to replace SREs with AI, but to explore how AI can become a new operational layer that helps engineers move from reacting to incidents toward more proactive and intelligent reliability engineering.
Bio
Alexandre Monteiro is an IT professional with more than 19 years of experience in technology, with a strong background in DevOps, SRE, Platform Engineering, Cloud Infrastructure, and automation.
Throughout his career, he has worked with enterprise environments and critical systems, focusing on cloud platforms, Kubernetes, Infrastructure as Code, CI/CD, observability, automation, and reliability engineering.
His experience includes working with Microsoft Azure, AWS, GCP, Kubernetes, Terraform, Azure DevOps, GitHub Actions, Prometheus, Grafana, and other cloud-native technologies.
More recently, Alexandre has been exploring the intersection between cloud operations, SRE, automation, and Generative AI, including AI agents and their potential applications in modern operational environments.
He is passionate about automation, reliability, cloud-native platforms, and the evolution of how engineering teams build and operate systems at scale.
Felipe Pereira
Máquina de Dados
Harness Engineering for Real: Building the Environment Where AI Can Actually Deliver
Abstract
AI is rapidly changing how data engineers write code, build pipelines, troubleshoot failures, and maintain complex data platforms. But getting real value from AI requires more than giving an agent access to a repository and asking it to generate code. Harness Engineering is about designing the environment around AI agents — providing the right context, tools, documentation, tests, observability, guardrails, and feedback loops so they can reliably understand, modify, validate, and operate data systems.
In this talk, we will explore what Harness Engineering looks like in the context of modern Data Engineering. From data contracts, schemas, lineage, and pipeline metadata to automated testing, CI/CD, observability, MCP, and agent-friendly repositories, we will discuss how to make data platforms AI-operable by design. The goal is to move from AI as a coding assistant to AI as an engineering collaborator: capable of diagnosing pipeline failures, implementing transformations, validating data quality, navigating complex dependencies, and safely contributing to production-grade data systems.
Bio
With two decades of experience in Information Technology, and postgraduate studies at FGV and Unicamp, Felipe Pereira is an Entrepreneur and Speaker. As an Entrepreneur, he has founded Máquina de Dados, a consultancy company that helps businesses be more strategic and innovative using Analytical Intelligence and Artificial Intelligence. He is also a Speaker, having lectured at major innovation & technology events such as Google Datafest and Singularity University.
Camilla Martins
Senior Site Reliability Engineer
Beyond the Default Scheduler: What PhD Research Taught Us About k8s Reliability with ML Prediction and Heuristics on GCP
Abstract
Reliability is not just about incident response—it starts with how workloads are placed and provisioned before failures even occur. This session breaks down the journey of translating academic doctoral research into hands-on testing inside Google Cloud infrastructure. We explore how heuristic models and predictive optimization can improve Kubernetes scheduling decisions, mitigate hot-spots, and prevent cascading node degradations. Through concrete benchmarks, test architectures, and post-experiment findings on GKE, this talk delivers actionable insights for SREs looking to optimize workload distribution, lower error budgets consumption, and balance theoretical guarantees with operational reality.
Bio
Camilla Martins is a Senior Site Reliability Engineer, Google Developer Expert (GDE), Docker Captain and Computer Science Ph.D. candidate at PPGI/UNIRIO. With extensive experience in cloud infrastructure, Kubernetes, and observability, her research focuses on applying optimization algorithms and heuristics to distributed cloud systems and container scheduling.
Gabriel Dantas Gomes
QuintoAndar
Transformando seu Kubernetes em um Cluster Agêntico com kagent
Abstract
Existe um desafio novo pros times de plataforma, SRE e DevOps: como escalar o uso de agentes de IA sem reinventar a roda a cada novo caso de uso? Construir um agente do zero tem curva de aprendizado real, e pra maioria dos problemas do dia a dia isso nem é necessário. Um projeto como o kagent já resolve a complexidade operacional e de segurança de rodar agentes como workloads de produção, sem você criar e sustentar um serviço próprio do zero. O kagent, projeto CNCF da Solo.io, trata agentes como recursos nativos do Kubernetes: CRDs gerenciados via kubectl e GitOps, rodando sobre um service mesh pra mTLS e RBAC, com descoberta nativa de ferramentas via MCP e comunicação Agent-to-Agent (A2A) pra agentes se encontrarem e delegarem tarefas entre si pelo cluster. A talk cobre a arquitetura (control plane, agent substrate, suporte a múltiplos runtimes como Go, Python, LangGraph, CrewAI), como a descoberta via A2A funciona na prática, e o que surpreende quem está começando.
Bio
Gabriel Dantas é Platform Engineer (DevEx & Productivity) no QuintoAndar, com 6+ anos de experiência em Developer Experience e Platform Engineering. Ajuda a construir e manter um Internal Developer Platform baseado em Backstage, atendendo mais de 500 engenheiros e engenheiras. No dia a dia trabalha com Kubernetes, ArgoCD e observability via OpenTelemetry. Já palestrou em Platform Days, DevOpsDays São Paulo e DevPR.
Rodrigo Leme
Microsoft
Melhorando Reliability Através AI-Powered Application Modernization com GitHub
Abstract
Aplicações legadas frequentemente se tornam fonte de sobrecarga operacional, exposição a riscos de segurança e desafios de confiabilidade. Nesta sessão, exploraremos como a modernização de aplicações com o GitHub pode acelerar iniciativas de modernização utilizando transformação, testes e validação de código assistidos por IA. Por meio de exemplos reais e lições aprendidas, mostraremos como os esforços de modernização podem aumentar a confiabilidade do sistema, reduzir riscos operacionais e permitir que as equipes de engenharia dediquem menos tempo a resolver problemas emergenciais e mais tempo a gerar valor.
Bio
Especialista em Engenharia de Soluções na Microsoft, Rodrigo Leme acumula uma sólida trajetória de duas décadas liderando projetos de infraestrutura de TI, Governança de Nuvem Híbrida e Transformação Digital. Com histórico internacional e atuação prévia como consultor sênior na IBM e Kyndryl, ele possui visão ampla sobre otimização de custos e arquitetura de negócios. Rodrigo é reconhecido por conectar tecnologia de ponta aos objetivos comerciais de grandes organizações, garantindo escalabilidade, segurança e eficiência financeira.
Derick Rodrigues
Ana Gaming
Do provisionamento manual aos golden paths: migrando para EKS e CloudFront com Backstage
Abstract
Em um ambiente AWS pouco padronizado, aplicações eram publicadas em ECS e Amplify por meio de processos manuais, com configurações descentralizadas e diferentes níveis de segurança e observabilidade. Precisávamos aumentar a confiabilidade da plataforma sem transformar o time responsável em um gargalo, e principalmente, sem retirar a autonomia dos desenvolvedores. Nesta palestra, apresentarei a jornada de migração para uma arquitetura baseada em EKS e CloudFront e como utilizamos o Backstage para criar uma experiência de autosserviço. Por meio de Software Templates e pipelines de CI/CD, transformamos padrões arquiteturais, requisitos de segurança, observabilidade e mecanismos de rollback em golden paths reutilizáveis. Mostrarei como estruturamos templates de frontend e backend alinhados às tecnologias da empresa, permitindo que novas aplicações fossem implantadas em poucos minutos. Também compartilharei os desafios, as decisões arquiteturais, os trade-offs da adoção do EKS e os aprendizados de centralizar a experiência do desenvolvedor sem centralizar todo o trabalho em uma única equipe.
Bio
Direto da terra do peão, é apaixonado por tecnologia e por seu potencial de simplificar o dia a dia. Graduado em Sistemas de Informação pela PUC Minas, atualmente é mestrando em Tecnologias da Informação e Comunicação e Gestão do Conhecimento, enquanto mantém um flerte cada vez mais sério com a carreira acadêmica. É fundador do AWS SGB PUC Minas e organizador do DevOpsDays BH. Nas horas vagas, especializa-se em piadas ruins, cultiva sua paixão pela cultura nerd e tenta praticar esportes, apesar de as aparências insistirem em dizer o contrário.
Joao Gabriel Franchi Briotto & Leonardo Camara
Banco Bradesco
Where no Postmortem has gone before: The Resilience Sprint Journey
Abstract
Here at Bradesco we run a process called Resilience Sprint. In this process we look into one application per month, put devs, SRE, observability, Archtecture, ITSM and Infra people together in one room and look for SPOFs, Archtecuture flaws (technical debt), problems that hasnt been prioritized and make a list of actions to complete in 4 weeks. We have everybody looking at the same direction. My team controls and conduct the ritual and make sure we generate value. Would like a spot to explain how those things works.
Bio
Joao is a senior analyst that is responsible for the resilience culture, implanted in 2025. He runs e conects the priorities with senior executives.
Emerson Silva
4Linux
Talos Linux: um OS imutável e sem SSH para o Kubernetes
Abstract
A maioria dos clusters Kubernetes ainda roda em sistemas operacionais tradicionais — com SSH aberto, pacotes desnecessários e superfície de ataque enorme. O Talos Linux resolve isso na raiz: um OS construído do zero exclusivamente para Kubernetes, sem shell, sem SSH, com sistema de arquivos imutável e gerenciado inteiramente por API gRPC declarativa. Nesta palestra vamos entender a filosofia do Talos — efêmero, seguro por design, 100% declarativo — e por que isso importa pra quem opera confiabilidade em produção. Com uma demo prática subindo um cluster local, você vai sair sabendo se o Talos faz sentido no seu ambiente, e como avaliar essa migração sem drama.
Bio
Emerson Silva é Engenheiro DevOps/SRE na 4Linux, com mais de 9 anos de experiência em ambientes críticos de infraestrutura, automação e confiabilidade. Instrutor, autor e palestrante, com passagens por SREDay, DevOpsDays e Meetups da CNCF. Community Lead de Kubernetes na DOUGBrazil e organizador dos eventos da CNCF Campinas.
Marcelo da Silva Pires
Denkyem Labs
Speed up Cloud Learning speding no money
Abstract
In this talk I will present how you can speed your AWS spending no money via self-hosted emulator. I will show why this is a great knowledge to have in your utility bealt and have a little IaC hands-on showing its capabilities.
Bio
Desenvolvedor, entusiasta da cultura DevOps, durante a sua carreira em Ti já trabalho em diversos segmentos como treinamento, sysadmin e desenvolvedor.
Willian Bersch Yamashita
Bradesco
A noite em que tudo quase parou - 3 níveis de maturidade no uso de IA
Abstract
Está apresentação propõe uma narrativa prática e provocativa sobre como a inteligência artificial pode transformar a sustentação de produtos de tecnologia em data centers. A partir de uma história fictícia, mas inspirada em desafios reais de operação, acompanhamos uma madrugada crítica em que uma degradação silênciosa coloca uma equipe de sustentação sob alta pressão.
Bio
Willian Bersch Yamashita é um Especialista SRE no Bradesco, onde se dedica a construir sistemas confiáveis de alto desempenho para uma das maiores instituições financeiras do Brasil. Com mais de 15 anos de experiência em. Desenvolvimento de software e engenharia de sistemas, já atuou em todas as camadas tecnológicas, desde o desenvolvimento de aplicativos móveis em kotlin e swift, ate sistemas backend de grande escala construídos com Spring. Aprimorando continuam te o desempenho estabilidade e a experiência do usuário em plataformas complexas. Com base em São Paulo, é reconhecido por conciliar confiabilidade e performance com uma engenharia bem elaborada e criteriosa.
Flavio Meira
Orca Security
Assinando tudo: Sigstore, Cosign e proveniência (provenance) em pipelines GitOps
Abstract
Um artefato não assinado que chega em produção não é apenas uma falha de segurança, é um incidente de disponibilidade esperando para acontecer. Em pipelines GitOps, confiamos implicitamente que a imagem no registry é exatamente a que o pipeline gerou, mas raramente verificamos isso de fato. Quando esse pressuposto falha, o sintoma aparece longe da causa: um SLO quebra, um rollback não se comporta como esperado e o time de plantão descobre tarde demais que a versão anterior nunca foi verificada com certeza. Com agentes de IA cada vez mais escrevendo e até fazendo commit de código, essa pergunta fica ainda mais urgente: seu pipeline consegue garantir que qualquer artefato, escrito por humano ou por IA, passou pelos mesmos gates de qualidade e segurança antes de chegar em produção? Nesta talk vamos entender como o Sigstore e o Cosign funcionam na prática, eliminando a necessidade de gerenciar chaves privadas manualmente na assinatura de artefatos. Vamos ver também como provenance, através das SLSA attestations, funciona como telemetria de como um artefato foi construído, não apenas de quem o assinou.
Bio
Flávio é especialista em segurança da informação em ambientes cloud (Azure, AWS), desenvolvimento seguro e DevOps. Tem ampla experiência em segurança de ambientes cloud e on-premise, segurança de containers e Kubernetes, além de práticas seguras de GitOps. Como desenvolvedor com foco em segurança, contribuiu em diversos projetos implementando gates de segurança em pipelines de CI/CD e aplicando shift-left no desenvolvimento seguro.
Marcelo Capile
IBM
Diagnose, Approve, Remediate, Verify: A Two-Agent AIOps Loop for Kubernetes
Abstract
Kubernetes incidents usually start the same way: an alert fires, someone checks events, runs a few describe and logs commands, builds a hypothesis, and decides whether it's safe to take action. Although this process is familiar to most SREs, it is still largely manual, time-consuming, and often difficult to document consistently. In our team, we started asking a simple question: how much of that investigation could be automated while still keeping humans in control of critical decisions? This talk presents a two-agent AIOps architecture designed around that idea. A collector monitors Kubernetes Warning events and triggers a read-only diagnostic agent. Through Kubernetes tools exposed by MCP, the agent gathers evidence, investigates affected resources, analyzes possible causes, and generates a structured incident report that an operator can review. The key design decision was to separate diagnosis from remediation. The diagnostic agent can investigate and suggest actions, but it cannot make changes. The operator remains responsible for deciding whether a proposed remediation is appropriate. Only after explicit approval does a second agent perform the corrective action. Every step is tracked. The system validates the cluster state after remediation, records the outcome, and preserves reports, decisions, failures, and state transitions to provide a complete audit trail.
Bio
Marcelo Capilé is an SRE and Infrastructure Architect at IBM with more than 15 years of experience in IT. His background includes Linux, AIX, automation, cloud infrastructure, observability, Kubernetes, and Red Hat OpenShift, with a strong focus on solving operational problems in complex environments. He is a Certified Kubernetes Administrator (CKA) and a Red Hat Certified Architect (RHCA), specializing in OpenShift. Marcelo also contributed to the IBM Redbook Implementation Guide for Kubernetes and Red Hat OpenShift, covering the implementation of IBM Storage Scale Container Native (CNSA), and is a contributing author of Jornada Kubernetes, a collaborative Brazilian book about Kubernetes. He enjoys turning operational challenges into practical solutions and sharing what he learns through technical communities, mentoring, writing, and collaborative projects.
Igor Estevan Jasinski
Sicredi
Observability as a Service: How Sicredi Transformed Monitoring into a Self-Service Platform
Abstract
Modern engineering teams need observability, but building and maintaining monitoring infrastructure shouldn't be their primary focus. This talk presents how Sicredi, one of Brazil's largest cooperative financial institutions, transformed observability from a complex technical requirement into a consumable service through their Internal Developer Platform (IDP). We'll explore the journey from fragmented monitoring tools to a unified observability platform that offers instrumentation modules, SLO management, forecasting, anomaly detection, and AI-powered insights as self-service capabilities. Attendees will learn practical strategies for abstracting observability complexity while empowering development teams with powerful monitoring capabilities
Bio
Passionate about observability, distributed systems, and open source, I lead observability initiatives at Sicredi, where I focus on building an Observability as a Service platform for engineering teams. I enjoy sharing practical experiences from designing and operating observability platforms at scale, helping organizations improve reliability, accelerate incident response, and foster an observability-first culture.
Osanam Giordane da Costa Junior
Cloud Agil Tech
Autonomous SRE agents at observability
Abstract
In this talk I'll demonstrate how AI agents can help SRE for validate K8s app errors and send option to resolve problem or resolv manually with this AI copilot.
Bio
Microsoft MVP, AWS Community Builder and Hashicorp Ambassador. +25 years on technology. DevOps and Cloud Engineer. Partipating at big projects of automate using IAC, pipelines and now using AI fo AIOps.