SREday is a worldwide series of community events for engineers who build, ship and run modern software systems. Across cities around the world, we bring together people working in reliability, cloud, DevOps, observability and production engineering to share real-world experience, connect with their local community and explore how these disciplines are evolving in the age of AI.
As AI agents increasingly generate and deploy code into production, the traditional DevOps mantra "Code it. Ship it. Own it." is being disrupted. In this talk, I will explore how agentic AI is changing the software development lifecycle and what happens when AI “owns” large portions of the pipeline.
Code development, operational knowledge and even incident response are increasingly being delegated to AI systems, but that doesn't guarantee infallibility! What happens when it breaks and nobody has seen the code before?
I will examine how AI is already changing both software engineering and SRE practices, where the advances are effective and where human expertise remains critical. I will challenge you to rethink how we do service ownership, what skills are required for SREs in the agentic age, and how to collaborate with AI to ensure resilient, trustworthy systems.
Is the DevOps revolution over, or are we simply at its next frontier?... Read more
AI applications promise transformative capabilities but introduce unique failure modes, such as hallucinations, latency spikes, data drift, and cost overruns, that traditional SRE practices don't fully address. This session explores proven reliability patterns, retries with exponential backoff, circuit breakers, graceful degradation, and human-in-the-loop guardrails tailored for Microsoft Foundry workloads, where observability covers agent traces, quality metrics, and safety evaluations. You'll see live demos of implementing these in Foundry projects using zone-redundant storage, multi-region failover, and built-in content filters to achieve production-grade resilience while maintaining trust and compliance.... Read more
Remember when you knew all your servers by name and deployed changes with a single SSH command? Now imagine doing that when your link comes in 10-minute windows every few hours, and bandwidth is a precious commodity measured in kbps. Welcome to DevOps in Space. At Sateliot, our Infrastructure & Software Engineering team works at the intersection of aerospace, telecommunications and software. We build modern distributed systems and then send them to an environment where normal expectations -low latency, immediate feedback, up-to-date systems- simply don’t apply. In this talk I’ll give a high-level tour of the challenges that make space and telco different: intermittent and low-bandwidth connectivity, long feedback loops, constrained devices, and the cultural gaps between aerospace, telco and software teams. I'll also share some adaptations that allow us to apply some of the DevOps processes and tools that have become industry standards.... Read more
DevOps is widely adopted in name, but successful adoption in practice remains uneven across organizations. In this talk, I will present the main outcomes of my PhD research on how IT organizations can improve DevOps adoption. I will focus on the capabilities, metrics, and lifecycle practices that have the strongest impact on delivery performance and operational reliability. I will share a practical framework that helps teams identify common adoption barriers, connect engineering practices to measurable outcomes, and design improvement strategies that support both faster delivery and more resilient operations. The session is intended for leaders and practitioners who want a clearer, evidence-based view of what makes DevOps work beyond tooling and slogans.... Read more
Every SRE team knows the drill. Prometheus for metrics. Loki for logs. Jaeger or Tempo for traces. Pyroscope bolted on last for profiling. Four services, four storage backends, four things to scale, debug, and pay for. And when an incident hits, you're jumping between all of them trying to correlate signals that were never designed to live together.The trade-off is always the same: observe everything and pay an astronomical bill, or cut costs and fly blind precisely when it matters most. We got tired of it. So we built Gigapipe. Gigapipe is an open-source polyglot observability stack that unifies logs, metrics, traces, and profiles on a single backend, using ClickHouse as the database. It natively implements the industry standards like Prometheus, Loki, Jaeger, Tempo, Pyroscope, and OpenTelemetry APIs, just to name a few. Your existing agents, exporters, and Grafana dashboards work on day one, unchanged. In this talk, we'll cover three things: 1. Why we built it: the real pain that made four services feel unsustainable, 2. How it works: the architecture decisions behind native multi-protocol compatibility on a single storage engine, 3. How you can get involved or run it yourself today: Gigapipe is open-source, under AGPLv3 license, runs as a single binary, and is live in production environments. This is a talk for engineers who've felt the weight of their observability stack and wondered if there's a better way. Spoiler: There is! And you can run it tonight.... Read more
You replace pods instead of patching them. So why is the OS underneath your nodes still the last hand-patched snowflake in an otherwise declarative stack? Image-based operating systems turn nodes into versioned artifacts that can be upgraded and rolled back predictably, reducing drift and making failure recovery part of the platform design rather than an incident-time improvisation. As a Kairos maintainer, I will show how this model works in practice: what remains immutable, what persists, how atomic upgrades and rollback work, and what happens when a node fails to boot. We will then use Kubernetes to drive an upgrade and rollback of an immutable node. Because application reliability is difficult enough without discovering during an incident that no one knows exactly what the node underneath it has become.... Read more
Logs, metrics and traces nowadays are common words in every engineer's vocabulary, as Observability is everywhere with the rise of OpenTelemetry and improved standards. Instrumentation? No problem. Getting data from any system? Done. But then soon after, things start to fall apart, telemetry piles up unused, cloud bills soar, dashboards rot and alerts confuse even seasoned engineers. Clearly there is something missing. In this talk, Iris and Hélia share some experiences from building Observability platforms, patterns they have discovered of how users interact with telemetry data. From common questions across different teams and companies, pitfalls and also, strategies that empower teams to move from confusion to confidence. So get practical insights to bridge the gap between Observability data and User Knowledge, whether you're building platforms, supporting teams, or trying to make sense of your own telemetry chaos.... Read more
Cloud infrastructure incidents are often hard to troubleshoot because the problem is not always visible from the application layer. A service may look healthy, the instances may be running, and the dashboards may not clearly show the issue, but connectivity can still fail because of routing, security rules, DNS, or cloud configuration problems.
In this talk, I will show how AI-assisted workflows can support SREs and cloud engineers during infrastructure troubleshooting. The focus is not on using AI to replace engineering judgment, but on using it to investigate faster, ask better questions, review configuration, interpret CLI output, and reduce the time spent jumping between documentation, consoles, and logs.
As a practical demo, I will use AWS MCP servers to investigate a real-world style cloud connectivity issue and work toward the root cause. We will look at what context is useful to give the AI assistant, how MCP can help connect the assistant to AWS documentation and environment information, and where the engineer still needs to validate the output.
The goal is to give attendees a realistic view of what AI can and cannot do during real infrastructure incidents. The session will focus on practical troubleshooting patterns, safe usage of AI during production-like investigations, and the importance of human validation when dealing with cloud reliability and infrastructure security.... Read more
Running AI agents in production looks nothing like the demos. Over the past 18 months I have shipped four production AI systems as a solo engineer - multi-tenant customer service on WhatsApp, invoice extraction pipelines, HR automation, and an agent fleet management tool. Each one broke in ways I did not expect.
This talk is a practical post-mortem on the failure modes that matter in production AI: LLM calls that silently return wrong answers with high confidence, cascading cost spikes that signal upstream failures before users notice, and observability gaps that make debugging a model’s decision nearly impossible. I will walk through the reliability patterns that actually helped - confidence cascades that cut cost per document by 85%, human-in-the-loop as a circuit breaker rather than a fallback, and treating AI coding agents as infrastructure with explicit boundaries.
No benchmarks, no theory. Just what breaks, why it breaks, and what I changed.... Read more
Following Easter 2024, our messaging platform underwent a significant transformation. This presentation explores how an engineering team transitioned from developing a simple messaging product to constructing a phishing detection platform. More importantly, how we adopted a mindset akin to fraudsters, always brainstorming potential attack vectors. Join us at this engineering storytelling session that delves into how Tripadvisor leveraged straightforward tools such as text analysis, domain detection and asynchronous processing to implement a phishing detection capability while maintaining a seamless user experience.... Read more
17:00
Wrap up
Scan each other's QR codes & head to a nearby pub!
Allo | Alcântara Lisbon Offices, Av. da Índia 10,
1300-299 Lisboa, Portugal
Sponsors & Partners
Want to become a sponsor? Get in touch!
Tiago Costa
Azure Cloud & AI Architect and Advisor
Reliability Patterns for AI-Powered Apps in Azure AI Foundry
Abstract
AI applications promise transformative capabilities but introduce unique failure modes, such as hallucinations, latency spikes, data drift, and cost overruns, that traditional SRE practices don't fully address. This session explores proven reliability patterns, retries with exponential backoff, circuit breakers, graceful degradation, and human-in-the-loop guardrails tailored for Microsoft Foundry workloads, where observability covers agent traces, quality metrics, and safety evaluations. You'll see live demos of implementing these in Foundry projects using zone-redundant storage, multi-region failover, and built-in content filters to achieve production-grade resilience while maintaining trust and compliance.
Bio
Tiago Costa is an Azure Cloud and AI Architect, advisor, trainer, public speaker, and author based in the Lisbon Metropolitan Area. As an independent contractor, he helps organizations design and optimize cloud and AI strategies, with a strong focus on Microsoft Azure technologies. He is also recognized for educating technical audiences through training, speaking engagements, and thought leadership.
David Jacovkis
Sateliot
DevOps in Space: Lessons from Low Earth Orbit
Abstract
Remember when you knew all your servers by name and deployed changes with a single SSH command? Now imagine doing that when your link comes in 10-minute windows every few hours, and bandwidth is a precious commodity measured in kbps. Welcome to DevOps in Space. At Sateliot, our Infrastructure & Software Engineering team works at the intersection of aerospace, telecommunications and software. We build modern distributed systems and then send them to an environment where normal expectations -low latency, immediate feedback, up-to-date systems- simply don’t apply. In this talk I’ll give a high-level tour of the challenges that make space and telco different: intermittent and low-bandwidth connectivity, long feedback loops, constrained devices, and the cultural gaps between aerospace, telco and software teams. I'll also share some adaptations that allow us to apply some of the DevOps processes and tools that have become industry standards.
Bio
I started as a sysadmin when workloads ran on bare metal and Devs were the enemies of Ops. The industry changed and we changed with it, but at the end of the day we're still the ones that receive an alert when things stop working.
Ricardo Amaro
Elastic
From DevOps Adoption to Reliable Delivery
Abstract
DevOps is widely adopted in name, but successful adoption in practice remains uneven across organizations. In this talk, I will present the main outcomes of my PhD research on how IT organizations can improve DevOps adoption. I will focus on the capabilities, metrics, and lifecycle practices that have the strongest impact on delivery performance and operational reliability. I will share a practical framework that helps teams identify common adoption barriers, connect engineering practices to measurable outcomes, and design improvement strategies that support both faster delivery and more resilient operations. The session is intended for leaders and practitioners who want a clearer, evidence-based view of what makes DevOps work beyond tooling and slogans.
Bio
Ricardo Amaro is an Engineering Manager at Elastic, a PhD in Information Technologies, an O’Reilly author, and a university visiting professor at Técnico and ISCTE. He has spent his career working across software engineering, infrastructure, and operations, with a strong focus on DevOps, reliability, and large-scale systems. Ricardo is also President of the Portuguese Drupal Association.
Rita Lopes
Gigapipe
404: Observability Without Trade-offs Not Found - Until We Built Gigapipe
Abstract
Every SRE team knows the drill. Prometheus for metrics. Loki for logs. Jaeger or Tempo for traces. Pyroscope bolted on last for profiling. Four services, four storage backends, four things to scale, debug, and pay for. And when an incident hits, you're jumping between all of them trying to correlate signals that were never designed to live together.The trade-off is always the same: observe everything and pay an astronomical bill, or cut costs and fly blind precisely when it matters most. We got tired of it. So we built Gigapipe. Gigapipe is an open-source polyglot observability stack that unifies logs, metrics, traces, and profiles on a single backend, using ClickHouse as the database. It natively implements the industry standards like Prometheus, Loki, Jaeger, Tempo, Pyroscope, and OpenTelemetry APIs, just to name a few. Your existing agents, exporters, and Grafana dashboards work on day one, unchanged. In this talk, we'll cover three things: 1. Why we built it: the real pain that made four services feel unsustainable, 2. How it works: the architecture decisions behind native multi-protocol compatibility on a single storage engine, 3. How you can get involved or run it yourself today: Gigapipe is open-source, under AGPLv3 license, runs as a single binary, and is live in production environments. This is a talk for engineers who've felt the weight of their observability stack and wondered if there's a better way. Spoiler: There is! And you can run it tonight.
Bio
I started my career staring at SIP traces at 2am wondering why calls were dropping. I spent years inside telecommunications and real-time communications infrastructure. From those years, I spent a lot of time looking at observability and monitoring tools. So, why not make the switch from the person who stares at those tools to the person who builds them? Joining QXIP (the team behind the coolest and most creative open-source code out there) was even better than I anticipated, because that was the decision that made Gigapipe possible. Why settle for a tool to observe RTC traffic if I can build one that does full-stack observability? And then there was Gigapipe. Gigapipe is an open-source polyglot observability solution: logs, metrics, traces and profiles. Your data, your infrastructure, your rules. Made by engineers for engineers. I still read the SIP traces. Old habits. MSc in Electrical and Computer Engineering. Certified in many things (I'm a sucker for certifications). Permanently curious.
Mauro Morales
Spectro Cloud
From Boot to Rollback: How Image-Based Operating Systems Change Kubernetes Operations
Abstract
You replace pods instead of patching them. So why is the OS underneath your nodes still the last hand-patched snowflake in an otherwise declarative stack? Image-based operating systems turn nodes into versioned artifacts that can be upgraded and rolled back predictably, reducing drift and making failure recovery part of the platform design rather than an incident-time improvisation. As a Kairos maintainer, I will show how this model works in practice: what remains immutable, what persists, how atomic upgrades and rollback work, and what happens when a node fails to boot. We will then use Kubernetes to drive an upgrade and rollback of an immutable node. Because application reliability is difficult enough without discovering during an incident that no one knows exactly what the node underneath it has become.
Bio
Mauro Morales is a Staff Engineer at Spectro Cloud working on Linux systems designed for cloud-native and edge platforms. His focus is on the operating system layer — building foundations that allow Kubernetes environments to run securely, predictably, and with minimal operational friction. He is a maintainer of the CNCF Sandbox project Kairos, co-host of the Cloud Native Brussels community group, and a member of the TAG Workloads Foundation. Originally from Guatemala, he now lives in Belgium with his family.
Helia Barroso & Iris Dyrmishi
Five9 & Miro
Observability Through Users' Eyes and How to Fix the Knowledge Disconnect
Abstract
Logs, metrics and traces nowadays are common words in every engineer's vocabulary, as Observability is everywhere with the rise of OpenTelemetry and improved standards. Instrumentation? No problem. Getting data from any system? Done. But then soon after, things start to fall apart, telemetry piles up unused, cloud bills soar, dashboards rot and alerts confuse even seasoned engineers. Clearly there is something missing. In this talk, Iris and Hélia share some experiences from building Observability platforms, patterns they have discovered of how users interact with telemetry data. From common questions across different teams and companies, pitfalls and also, strategies that empower teams to move from confusion to confidence. So get practical insights to bridge the gap between Observability data and User Knowledge, whether you're building platforms, supporting teams, or trying to make sense of your own telemetry chaos.
Bio
DevOps/SRE with a background in Biotechnology and a strong passion for Observability. Maintainer of Prometheus Operator and active contributor to open source projects including Perses. Community organizer for Cloud Native Porto. Curious by nature, always learning and exploring new challenges in the cloud-native ecosystem.
Pooria Ghaedi
Miniclip
AI-Assisted Cloud Troubleshooting
Abstract
Cloud infrastructure incidents are often hard to troubleshoot because the problem is not always visible from the application layer. A service may look healthy, the instances may be running, and the dashboards may not clearly show the issue, but connectivity can still fail because of routing, security rules, DNS, or cloud configuration problems.
In this talk, I will show how AI-assisted workflows can support SREs and cloud engineers during infrastructure troubleshooting. The focus is not on using AI to replace engineering judgment, but on using it to investigate faster, ask better questions, review configuration, interpret CLI output, and reduce the time spent jumping between documentation, consoles, and logs.
As a practical demo, I will use AWS MCP servers to investigate a real-world style cloud connectivity issue and work toward the root cause. We will look at what context is useful to give the AI assistant, how MCP can help connect the assistant to AWS documentation and environment information, and where the engineer still needs to validate the output.
The goal is to give attendees a realistic view of what AI can and cannot do during real infrastructure incidents. The session will focus on practical troubleshooting patterns, safe usage of AI during production-like investigations, and the importance of human validation when dealing with cloud reliability and infrastructure security.
Bio
Pooria Ghaedi is a Senior Cloud Engineer focused on cloud infrastructure, reliability, infrastructure security, and automation. He works on designing and improving scalable cloud platforms, with a strong interest in practical troubleshooting and operational excellence. He is an AWS Community Builder in the Networking & Content Delivery category and writes about cloud engineering, infrastructure security, and AI-assisted engineering workflows.
Miguel Borges
UNREAL Performance
AI Agents in Production: What Actually Breaks
Abstract
Running AI agents in production looks nothing like the demos. Over the past 18 months I have shipped four production AI systems as a solo engineer - multi-tenant customer service on WhatsApp, invoice extraction pipelines, HR automation, and an agent fleet management tool. Each one broke in ways I did not expect.
This talk is a practical post-mortem on the failure modes that matter in production AI: LLM calls that silently return wrong answers with high confidence, cascading cost spikes that signal upstream failures before users notice, and observability gaps that make debugging a model’s decision nearly impossible. I will walk through the reliability patterns that actually helped - confidence cascades that cut cost per document by 85%, human-in-the-loop as a circuit breaker rather than a fallback, and treating AI coding agents as infrastructure with explicit boundaries.
No benchmarks, no theory. Just what breaks, why it breaks, and what I changed.
Bio
Miguel Borges is an AI engineer and founder of UNREAL Performance, an AI implementation studio based in Lisbon. Over the past 18 months he has shipped four production AI systems using Anthropic Claude, OpenAI, Supabase, n8n, and Cloudflare Workers. He recently submitted a 35-page technical write-up to the Augusta Labs Arcus Prize - a reverse engineering challenge on a Portuguese-literature language model - which drew a personal response from the co-founder. Before moving into AI engineering, he spent five years as Senior Manager at Concentrix scaling customer experience operations for Fortune 500 clients across Europe.
Tiago Rodrigues
Tripadvisor
How Easter sparked the hunt for villains
Abstract
Following Easter 2024, our messaging platform underwent a significant transformation. This presentation explores how an engineering team transitioned from developing a simple messaging product to constructing a phishing detection platform. More importantly, how we adopted a mindset akin to fraudsters, always brainstorming potential attack vectors. Join us at this engineering storytelling session that delves into how Tripadvisor leveraged straightforward tools such as text analysis, domain detection and asynchronous processing to implement a phishing detection capability while maintaining a seamless user experience.
Bio
Tiago Rodrigues is a Java Developer with more than 15 years of experience. After almost 6 years at TripAdvisor, he decided that just programming wasn't as fun and became the manager of a team of 7 people. And now, between 1:1, planning meetings and - of course - fraudsters, he doesn't have time to code...
Joao Freitas
PagerDuty
Introduction, meet & greet
Abstract
Bio
João Freitas is General Manager and Engineering Lead for AI at Pager Duty. João leads PagerDuty AI initiatives and he is the main representative of the Lisbon office, being responsible for its growth, expansion, and culture. With about 20 years of experience in Software Development, Machine Learning, and as a People Manager, he was previously CTO at a startup in the area of Artificial Intelligence and has taken several roles at Microsoft in the areas of Speech Technologies and Data Engineering. João also holds a PhD in the areas of speech technology and human-computer interaction, filed several patents, and published over 40 articles in peer-reviewed international conferences and journals. He is also a regular speaker at AI conferences and the author and co-author of book chapters and one book.
Ralph Bird
PagerDuty
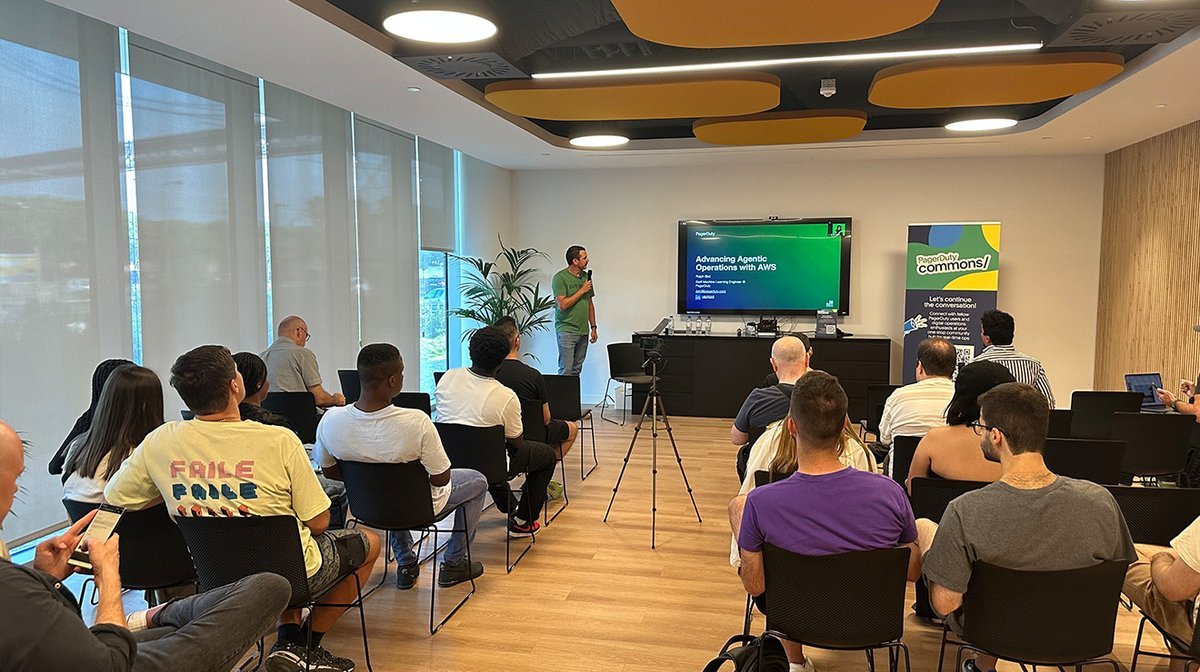
AI Coded It, AI Shipped It, Who Owns It? The Future of SREs in Agentic Operations
Abstract
As AI agents increasingly generate and deploy code into production, the traditional DevOps mantra "Code it. Ship it. Own it." is being disrupted. In this talk, I will explore how agentic AI is changing the software development lifecycle and what happens when AI “owns” large portions of the pipeline.
Code development, operational knowledge and even incident response are increasingly being delegated to AI systems, but that doesn't guarantee infallibility! What happens when it breaks and nobody has seen the code before?
I will examine how AI is already changing both software engineering and SRE practices, where the advances are effective and where human expertise remains critical. I will challenge you to rethink how we do service ownership, what skills are required for SREs in the agentic age, and how to collaborate with AI to ensure resilient, trustworthy systems.
Is the DevOps revolution over, or are we simply at its next frontier?
Bio
Ralph Bird is a Principal ML Engineer at PagerDuty, focused on AI agents, LLM observability, and production-grade AI systems. Previously an astrophysics researcher at UCLA and a nuclear safety engineer at Rolls-Royce, he now builds autonomous AI systems for high-stakes incident response and reliability workflows. Ralph combines deep technical expertise across machine learning, distributed systems, and software architecture with a strong background in research and engineering leadership.