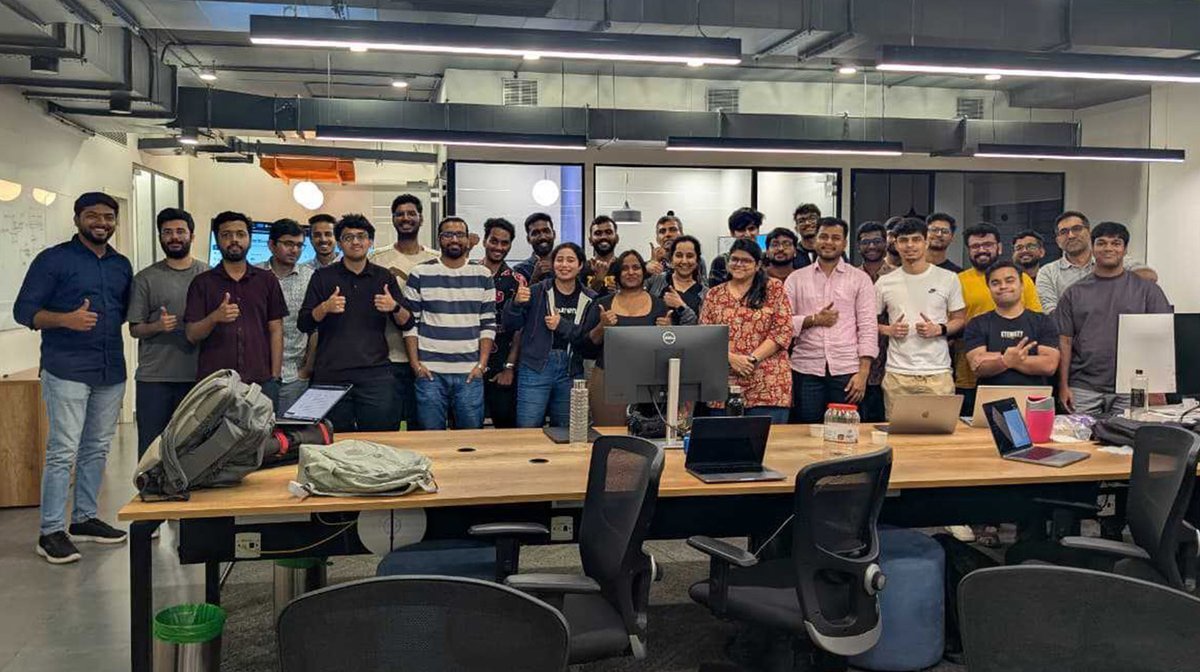
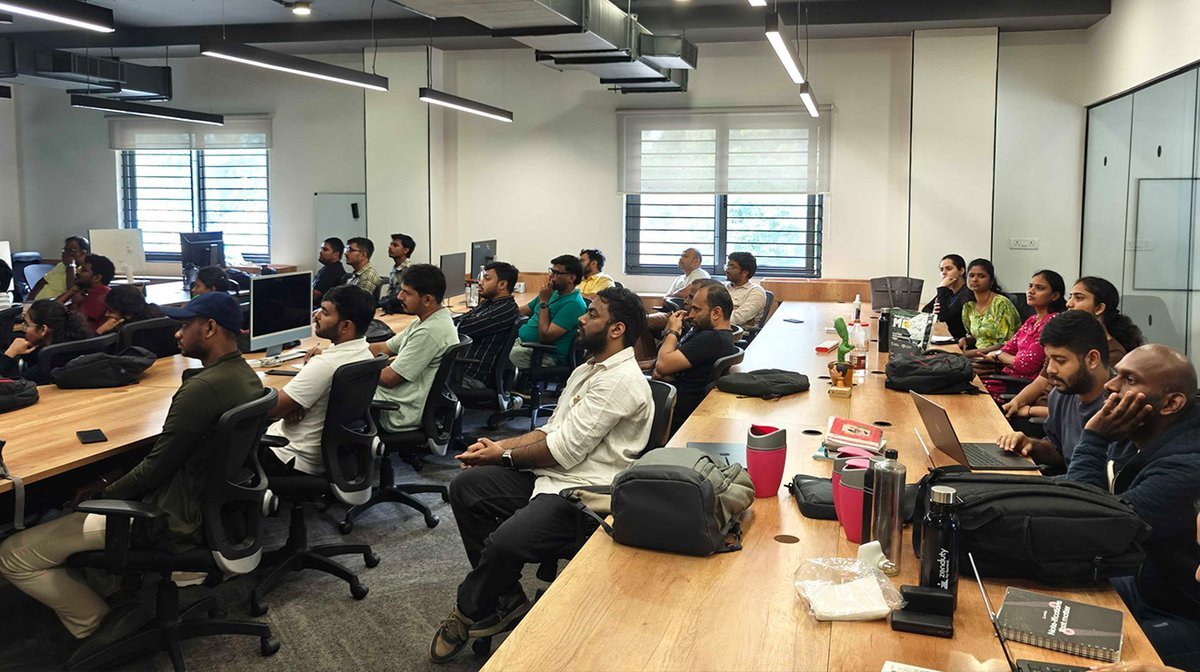
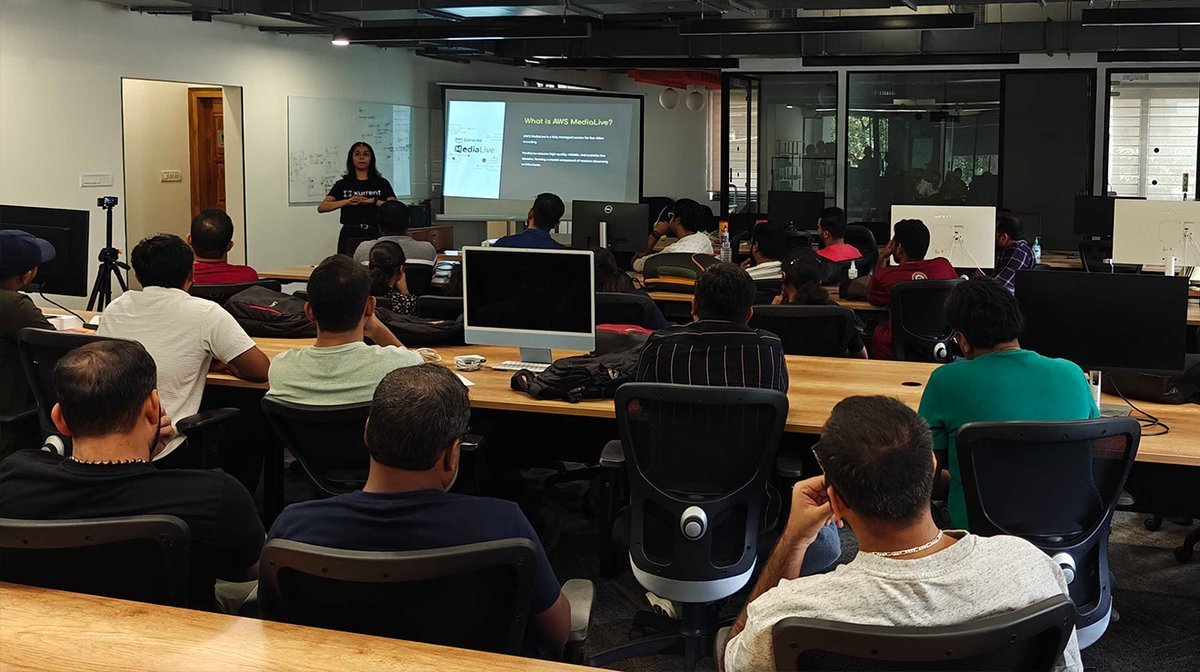
SREday is a worldwide series of community events for engineers who build, ship and run modern software systems. Across cities around the world, we bring together people working in reliability, cloud, DevOps, observability and production engineering to share real-world experience, connect with their local community and explore how these disciplines are evolving in the age of AI.
We're drowning in data but starving for insight. At peak load, we were collecting thousands of metrics per second, yet we still missed the signals that mattered. Worse, the observability overhead itself was creating garbage-collector pressure that degraded the systems we were trying to understand. The lesson we learned the hard way: observability isn't about collecting more data—it's about understanding the math behind the data and choosing the few signals that actually predict failure.... Read more
In this Keynote, Uma Mukkara, Head of Harness Resilience Testing and Co-Creator of LitmusChaos, explains why resilience must be built and tested throughout the Software Development Life Cycle, not treated as something to address after production issues occur.
He defines resilience as the ability of business services to withstand system failures, high load, and disasters, and shows how reduced resilience increases operational and business risk. The keynote introduces AI-powered resilience testing to help teams quantify risk, identify weaknesses early, and continuously measure, mitigate, and improve reliability across SDLC phases.
By combining chaos testing, load testing, and disaster recovery testing into a unified resilience strategy, Uma emphasizes that resilience is not optional. It must be proactively validated as a core practice of modern software delivery.... Read more
Everyone talks about scaling systems to millions of users. Few talk about what actually breaks first.
As organizations grow, the first bottlenecks rarely appear where expected. Databases run out of connections before they run out of CPU. Message queues quietly become storage systems. Observability platforms generate more data than the applications they monitor. Infrastructure scales, but operations struggle to keep pace.
In this session, we present a Reliability Scaling Framework based on real-world experiences navigating the journey from one million to thirty million users. Through practical examples and lessons learned, we explore how teams can identify and eliminate reliability bottlenecks across applications, data platforms, messaging systems, Kubernetes, observability, and operational workflows.
Beyond technology, we discuss why successful scaling requires organizational coordination and why the modern SRE must act as the captain of reliability—aligning engineers, architects, product teams, and executives toward a common goal while balancing availability, performance, and cost.
Attendees will gain a repeatable framework for assessing scalability readiness, preventing common reliability pitfalls, and building systems—and organizations—that can confidently support the next order of magnitude in growth.... Read more
Kubernetes clusters are often over-provisioned at the pod level, yet some workloads still experience CPU throttling. This usually comes from static CPU requests that are sized for worst-case behavior and rarely revisited once workloads are running. Recommendation-based systems exist, but applying frequent changes in production has traditionally been difficult due to restarts and operational risk. In-place pod resize makes it possible to update CPU requests without recreating pods, and PSI (Pressure Stall Indicator) metrics provide a clearer signal of real CPU contention. Together, these enable a different approach: making small, frequent, just-in-time corrections instead of relying on long-term prediction. In this talk, we share how we built CruiseKube, a runtime CPU optimization system that continuously right-sizes pods in place and takes node context into account. We discuss the key design choices, tradeoffs, and lessons learned from running this approach in real clusters.... Read more
For decades, infrastructure has behaved predictably. Control planes scheduled workloads, routed traffic, enforced policies, and executed deterministic logic engineers could reason about, debug, and trust. That assumption is beginning to change. As AI systems become embedded inside operational tooling, automation platforms, deployment workflows, and decision-making pipelines, infrastructure is slowly shifting from deterministic behavior toward probabilistic behavior. Modern systems can now generate actions instead of simply executing predefined logic. They can interpret intent, make recommendations, trigger workflows, and increasingly operate with partial autonomy. This introduces an entirely new class of reliability challenges. In this talk, we explore how AI-driven systems break many traditional assumptions of Site Reliability Engineering. Unlike conventional distributed systems, AI systems can fail silently while infrastructure metrics remain healthy. Outputs may vary between identical requests. Hallucinations, semantic drift, retrieval failures, and probabilistic decision-making create operational risks that existing observability practices were never designed to detect. This beginner-friendly session explores: * Why AI systems fail differently from traditional systems * The operational risks of probabilistic infrastructure * Hallucinations, semantic degradation, and silent failures * Why traditional monitoring is insufficient for AI-native systems * Emerging patterns for AI observability and reliability * What the future of SRE may look like in increasingly autonomous environments This talk is designed for SREs, platform engineers, DevOps practitioners, and cloud engineers interested in the future intersection of reliability engineering, AI systems, and autonomous infrastructure.... Read more
As digital systems become increasingly complex, traditional monitoring approaches are no longer sufficient to ensure reliability, performance, and user satisfaction. Monitoring began as a reactive practice focused on tracking predefined metrics, logs, and alerts to identify known issues. While effective for simpler environments, modern cloud-native architectures, microservices, distributed systems, and hybrid infrastructures have introduced unprecedented levels of scale and complexity. Observability emerged as the next evolution, enabling organizations to understand the internal state of systems through telemetry data such as metrics, logs, and traces. Unlike monitoring, observability provides deeper insights into unknown failures, dependencies, and performance bottlenecks, empowering teams to troubleshoot proactively and improve operational resilience. Today, Artificial Intelligence is transforming observability once again. AI-powered observability platforms leverage machine learning, predictive analytics, anomaly detection, and automated root cause analysis to process vast amounts of telemetry data in real time. These capabilities reduce alert fatigue, accelerate incident resolution, and enable predictive operations by identifying issues before they impact users. This evolution from monitoring to observability and now AI-driven observability represents a fundamental shift from reactive system management to intelligent, autonomous operations. Organizations that embrace AI-powered observability gain enhanced visibility, operational efficiency, and the ability to proactively manage increasingly dynamic digital ecosystems, paving the way for the future of self-healing and autonomous IT environments.... Read more
AI agents are starting to behave less like stateless chatbots and more like production systems: they call tools, mutate state, personalize behavior, and return to the same user or workflow over time. That creates a new reliability problem. When an agent remembers the wrong thing, the failure is subtle: future behavior changes, the prompt still looks reasonable, and the team may not know which prior read or write caused the issue. This beginner-friendly talk looks at agent memory from an SRE lens. We will walk through common failure modes such as stale memory, accidental overwrites, unbounded personalization, hidden prompt state, missing rollback, and poor auditability. Then we will discuss practical controls: explicit memory tools, scoped user/shared memory, revision history, access logs, safe write boundaries, and simple operational checks. I will use MemexAI, an open-source Postgres-backed memory layer for agents, as the demo system, but the focus is on reliability patterns teams can apply to any agent stack.
Attendees will learn:
- How agent memory can fail in production and why these failures are hard to debug
- A practical checklist for making agent memory inspectable, reversible, and observable
- How to think about agent memory as production state rather than prompt text... Read more
Observability data is hostile to general-purpose databases. Signals share a common profile: high write throughput, massive cardinality, time-series access patterns, and queries that scan billions of rows expecting sub-second answers. Most databases buckle under this combination. ClickHouse doesn't — but understanding why requires going deeper. In this session, we'll walk through the technical fundamentals that make ClickHouse uniquely suited for observability workloads: columnar storage and vectorised execution, the MergeTree family and TTL-based tiering, sparse indexing for time-range scans, and native ZSTD compression that routinely achieves 10–20× ratios on telemetry data. We will briefly touch the operational aspects of ClickHouse like shard topology and Replication. At the end of the session, the audience will leave with the takeaway of how to build and operate storage backend for modern observability data at scale.... Read more
Traditional automated remediation (if-this-then-that) is brittle. It fails when faced with the "unknown-unknowns" of distributed systems. When a production incident occurs, the cognitive load on the on-call engineer to parse logs, traces, and metrics is the primary bottleneck for MTTR (Mean Time to Resolution). But with the rise of Agentic AI—LLMs that don't just "chat" but actually execute tools—the dream of a truly self-healing infrastructure is finally within reach. This session moves past the marketing slides to demonstrate how to build an autonomous remediation pipeline that thinks like an SRE. We will explore the architecture of an0 Agentic Observability Loop. Unlike static scripts, an AI Agent can: Observe: Interface with AI Agents to identify the root cause. Reason: Cross-reference telemetry with recent GitHub deployments and runbooks. Act: Execute safe, scoped operations—like rolling back a canary, scaling a K8s deployment, or flushing a cache—using verified toolsets.... Read more
YAML is popular as a language for declarative configurations because of it's readability, support for hierarchical structure, and comments. However, hidden Unicode characters, homoglyphs, and bidirectional text controls can silently alter the behavior of infrastructure definitions, and CI/CD pipelines written in YAML. These invisible characters can evade code review, and even enable attacks that exploit the gap between what developers see and what machines interpret. In this talk, we'll explore real-world examples of rogue Unicode characters in YAML files, understand how they work, and practical defences — from linting, editor configuration and automated detection tools that can prevent these issues from reaching production.... Read more
Most engineers dream of writing code - but who keeps the code alive at 3 AM, making sure a million users never see a 500 error? That's the SRE, and the world can't hire them fast enough. This talk is a field-tested roadmap into Site Reliability and Platform Engineering, drawn from two decades of building SRE teams from scratch across multiple organizations.
We'll cover the two real paths in: the fresh graduate's 18-month journey from Linux fundamentals to first on-call rotation, and the career switcher's harder challenge - the mindset shift from "code is done when it compiles" to "code is done when it's observable in production." Attendees will walk away with the seven-pillar SRE competency matrix used in real hiring, the certifications that actually move the needle (and the ones that don't), and the interview signals that separate a true reliability engineer from a résumé.
Backed by data - 73% of high-performing orgs now run formalized SRE practices (DORA/Gartner), 25% YoY job growth, and Amazon losing ~$220K per minute of downtime - this session reframes SRE as the role of the decade. You'll leave with a concrete Week 1 starter pack to launch your own SRE origin story before you get home.... Read more
Site Reliability Engineering and DevOps teams are drowning in alerts, incidents, and repetitive tasks. What if AI agents could be your intelligent teammates, not just another tool in your stack? This talk explores the practical integration of AI agents into SRE and DevOps workflows, moving beyond hype to real-world implementation patterns. We'll examine how autonomous agents can transform incident response, automate runbook execution, and provide intelligent context during outages—all while maintaining the reliability standards SREs demand. Through live demonstrations and battle-tested patterns, you'll learn how to architect agent-based systems that integrate with your existing observability stack, handle multi-step troubleshooting workflows, and make decisions under pressure. We'll also explore AI DevOps Agent capabilities and how it helps teams reduce MTTR, automate toil, and scale operational excellence. Whether you're managing Kubernetes clusters, distributed systems, or cloud infrastructure, you'll leave with actionable strategies to augment your team with AI agents that actually work.... Read more
Modern production environments span Kubernetes, VMs, serverless, and event-driven systems, yet incident response still relies on manually stitching together dashboards, traces, and logs. While OpenTelemetry improves signal collection, it does not provide a consistent way to model dependencies across services, infrastructure, and asynchronous components. As a result, SREs spend valuable time correlating signals instead of identifying the root cause. This talk presents a graph-driven RCA approach built on a normalized observability layer that converts telemetry into relationships between services, infrastructure, and runtime events. Instead of treating traces, logs, and metrics independently, we derive a dependency graph enriched with time-based observations and health signals. This allows failures to be analyzed as propagation paths across systems rather than isolated alerts. We apply this approach to real-world scenarios across Kubernetes microservices, VM-based workloads, hybrid cloud environments, serverless platforms, and asynchronous systems such as Kafka. The graph highlights cascading failures, dependency latency, and hidden bottlenecks that are difficult to detect using traditional dashboards. We compare this workflow with trace-centric and metrics-first investigations, focusing on time-to-root-cause and operational effort during incidents. Attendees will learn how to build telemetry normalization layers, derive dependency graphs from observability data, and use graph-based reasoning to accelerate incident response. The session focuses on practical SRE workflows, design tradeoffs, and lessons learned from applying graph-driven RCA in distributed systems.... Read more
18:00
Wrap up
Scan each other's QR codes & head to a nearby pub!
Pre-production environments are often left running 24/7, leading to significant cloud waste—but safely automating their shutdown is more complex than it seems. Naive scheduling approaches can easily break dependencies, introduce inconsistent states, or make recovery unreliable. In this talk, I’ll present a real-world implementation of a scheduled, event-driven orchestration system on AWS that safely scales down and restores an entire pre-production environment. The solution uses EventBridge, Step Functions, and Lambda to coordinate state transitions across EC2, RDS, EBS, and application services. A key focus of this system is safe, state-aware execution. Each operation validates the current resource state before acting, ensuring that actions are effectively idempotent and safe to re-run. The workflow enforces dependency-aware sequencing and uses check/wait patterns to avoid acting on transitional or stale states, reducing the risk of unsafe shutdowns and restarts. Rather than relying on blind automation, this approach treats infrastructure changes as explicit, observable workflows, where failures are surfaced clearly and recovery paths are controlled. I’ll also share lessons learned around handling partial executions, the limitations of manual retry strategies, and why idempotency must be considered beyond individual steps. This session will provide practical insights into building reliable, cost-efficient infrastructure automation, along with design patterns that can be applied to any AWS-based environment.... Read more
In 2026, we're moving from Automated Ops to Agentic Ops — systems that reason, investigate, and remediate without human intervention.
In this demo-heavy session, I'll build a self-healing Kubernetes cluster live using CNCF projects — K8sGPT (auto-fixes cluster issues), HolmesGPT (investigates complex failures), and Kyverno (guardrails that control what the AI can touch). You'll watch an OOMKilled pod get auto-patched, a policy block the AI from touching critical workloads, and a cascading failure diagnosed with a full RCA delivered to your team's communication channel. You'll leave knowing what to automate, what to gate, and what to leave to humans.... Read more
Over the past year, we've been building and operating AI agents that help marketers analyze campaign performance and investigate why metrics change. While the demos looked impressive, production quickly exposed a different set of challenges: agents choosing the wrong tools, making unsupported assumptions, becoming expensive to run, and failing in ways traditional monitoring doesn't catch.
This talk will be a look at what worked, what didn't, and what surprised us while running AI agents in production.... Read more
This session will focus on how engineering organizations can design meaningful, actionable KPIs that improve reliability, operational excellence, and business outcomes.
Key discussion areas include:
- Why most KPIs fail
- Critical Success Factors (CSFs) and KPI alignment
- SRE and operational KPIs
- KPI anti-patterns and metric overload
- Governance and ownership models
- Practical lesson from enterprise-scale implementations
The session will be practical, experience-driven, and focused on applying KPIx framework methodology effectively in modern engineering and SRE environments.... Read more
Modern engineering teams rely on multiple tools for monitoring, incident management, security, compliance, and cloud operations. This session explores how AI can help SRE and Platform Engineering teams move from reactive troubleshooting to proactive and autonomous operations. Using a real-world platform engineering case study, I will demonstrate how observability, security insights, compliance checks, and automated remediation can be unified into a single operational workflow. Attendees will gain practical insights into reducing alert fatigue, improving incident response, enhancing reliability, and implementing AI-assisted operations in cloud-native environments.... Read more
Every team has an engineer who makes on-call look easy. They know the service that quietly degrades every Monday morning, the log pattern that precedes a cascade, and which alert has been firing incorrectly since the 2023 migration. When they leave, MTTR doubles and not because anything broke, but because the knowledge that made fast debugging possible was never captured. This talk is about making incident expertise durable. We cover how to extract the decision patterns that live in senior engineers' heads, encode them into investigation workflows that surface automatically during incidents, and measure whether the transfer is working. We walk through what worked, what created new toil (the "automated runbook" trap), and one incident where the system suggested the wrong root cause and why that was still a net win and more... Read more
While working with our customers, we are seeing that teams are shipping AI features fast but skipping the instrumentation that tells them what's actually happening in production.
AI applications fail differently from traditional services. Token exhaustion, retrieval quality drift, and provider outages don't show up in HTTP status codes. But how much instrumentation do you actually need, and when does the effort stop paying off?
To distill what we've learned from instrumenting customer AI applications, we built a reference RAG app and applied four levels of instrumentation: zero-code auto instrumentation, manual OTel spans, AI-native telemetry libraries, and an external AI gateway. Each level adds visibility but also adds effort, from zero lines of code to a production grade telemetry pipeline setup.
This talk presents a practical maturity model. For each level, we show: what you can now see, what failure modes you can catch, what's still invisible, and what it costs in engineering time. We use real traces and dashboards from a running system to ground the comparison.
Along the way, we bust some practical myths: why standard percentile calculations silently produce garbage for RAG similarity scores, and why "cheaper" models can end up costlier than premium ones in specific situations.
Whether you're deciding where to start or evaluating whether the next level of investment is worth it, you'll leave with a clear framework mapping effort to observability payoff, and a working open-source repo to validate it yourself.... Read more
Developers got disrupted by AI. They shrugged. SREs are next. They're terrified. The difference: a Copilot mistake is reverted in seconds. An autonomous AI system making remediation decisions in production is irreversible. One breaks a function. The other breaks trust in your infrastructure. But the real fear runs deeper. SREs have spent years building muscle memory around their systems—understanding failure modes, owning the reliability narrative. AI tooling promises to abstract that away. Use our platform. Upload your metrics. Trust our models. Your data lives in our cloud. Let us handle it. That's not autonomy. That's surrender. This talk cuts through the noise. We'll walk through why SRE fear of AI is rational, not paranoid. Why the current wave of 'AI SRE tools' are built for vendors, not operators. And why regulation (GDPR, data residency, compliance) is actually the key to building AI systems that SREs will adopt. The move: AI that lives where your systems live. On your infrastructure. Your data stays yours. Full transparency into every decision. Gradual autonomy—from suggest to execute-with-approval to autonomous. Built for regulated industries from day one. When privacy and control are baked in, AI stops being something that happens to you and becomes something you build. That's when SREs stop being scared and start being dangerous.... Read more
17:30
Wrap up
Scan each other's QR codes & head to a nearby pub!
Ground Floor, 581, 1st Main Rd, Sector 6, HSR Layout
Bengaluru, Karnataka 560102, India
Sponsors & Partners
Want to become a sponsor? Get in touch!
Raman Tehlan & Shubham Rai
Zurich Lab & Truefoundry
Unlocking Just-in-Time CPU Optimization with In-Place Pod Resize
Abstract
Kubernetes clusters are often over-provisioned at the pod level, yet some workloads still experience CPU throttling. This usually comes from static CPU requests that are sized for worst-case behavior and rarely revisited once workloads are running. Recommendation-based systems exist, but applying frequent changes in production has traditionally been difficult due to restarts and operational risk. In-place pod resize makes it possible to update CPU requests without recreating pods, and PSI (Pressure Stall Indicator) metrics provide a clearer signal of real CPU contention. Together, these enable a different approach: making small, frequent, just-in-time corrections instead of relying on long-term prediction. In this talk, we share how we built CruiseKube, a runtime CPU optimization system that continuously right-sizes pods in place and takes node context into account. We discuss the key design choices, tradeoffs, and lessons learned from running this approach in real clusters.
Bio
Raman Tehlan is a Cloud Native Consultant at Zurich Lab with over five years of experience building and operating distributed systems at scale. His work focuses on Kubernetes, cloud infrastructure, and developer platforms, with an emphasis on practical, production-ready solutions. He is also an active community contributor and an organizer of PyData Delhi, where he helps foster knowledge sharing around data, systems, and open-source technologies.
Shubham Rai is a Staff Software Engineer at TrueFoundry with 10 years of experience building Kubernetes and distributed systems. A contributor to KubeElasti, he focuses on reliability, cost efficiency, and DR at scale, sharing practical insights from real production systems.
Kaustubha Shravan
Microsoft
What Happens When the Control Plane Starts Thinking?
Abstract
For decades, infrastructure has behaved predictably. Control planes scheduled workloads, routed traffic, enforced policies, and executed deterministic logic engineers could reason about, debug, and trust. That assumption is beginning to change. As AI systems become embedded inside operational tooling, automation platforms, deployment workflows, and decision-making pipelines, infrastructure is slowly shifting from deterministic behavior toward probabilistic behavior. Modern systems can now generate actions instead of simply executing predefined logic. They can interpret intent, make recommendations, trigger workflows, and increasingly operate with partial autonomy. This introduces an entirely new class of reliability challenges. In this talk, we explore how AI-driven systems break many traditional assumptions of Site Reliability Engineering. Unlike conventional distributed systems, AI systems can fail silently while infrastructure metrics remain healthy. Outputs may vary between identical requests. Hallucinations, semantic drift, retrieval failures, and probabilistic decision-making create operational risks that existing observability practices were never designed to detect. This beginner-friendly session explores: * Why AI systems fail differently from traditional systems * The operational risks of probabilistic infrastructure * Hallucinations, semantic degradation, and silent failures * Why traditional monitoring is insufficient for AI-native systems * Emerging patterns for AI observability and reliability * What the future of SRE may look like in increasingly autonomous environments This talk is designed for SREs, platform engineers, DevOps practitioners, and cloud engineers interested in the future intersection of reliability engineering, AI systems, and autonomous infrastructure.
Bio
Kaustubha V is a Solution Architect at Microsoft in the Silicon Cloud organization, where she works on scalable cloud platforms, AI-driven systems, automation frameworks, and developer productivity solutions. Her work focuses on building reliable infrastructure and intelligent systems for large-scale engineering workloads across Azure and multi-cloud environments. At Microsoft, she designs solutions that use machine learning to optimize compute resources such as memory, runtime, and CPU requirements. She has contributed to production-grade ML pipelines, telemetry platforms, benchmarking frameworks, and cloud-native automation services that improve operational efficiency and simplify engineering workflows. Kaustubha has strong experience in Azure, AWS, Google Cloud, Kubernetes, distributed systems, and secure cloud deployments. She holds multiple cloud and AI certifications and has earned the Kubestronaut distinction from the Cloud Native Computing Foundation. Beyond her engineering role, Kaustubha is active in AI research and technology communities. Her research interests include generative AI, machine unlearning, responsible AI, and bias mitigation in machine learning systems. She has authored research papers accepted at international workshops and conferences, including NeurIPS,ICCV, GHC ICLR, GHCI, IEEE and leading data science venues. She is also passionate about mentoring and community impact. Through initiatives such as Women Techmakers and Microsoft’s Code Without Barriers, she supports students and early-career professionals in learning cloud computing, AI, and software engineering.
Faizana Samreen
Pearson
From Monitoring to AI: The Evolution of Observability
Abstract
As digital systems become increasingly complex, traditional monitoring approaches are no longer sufficient to ensure reliability, performance, and user satisfaction. Monitoring began as a reactive practice focused on tracking predefined metrics, logs, and alerts to identify known issues. While effective for simpler environments, modern cloud-native architectures, microservices, distributed systems, and hybrid infrastructures have introduced unprecedented levels of scale and complexity. Observability emerged as the next evolution, enabling organizations to understand the internal state of systems through telemetry data such as metrics, logs, and traces. Unlike monitoring, observability provides deeper insights into unknown failures, dependencies, and performance bottlenecks, empowering teams to troubleshoot proactively and improve operational resilience. Today, Artificial Intelligence is transforming observability once again. AI-powered observability platforms leverage machine learning, predictive analytics, anomaly detection, and automated root cause analysis to process vast amounts of telemetry data in real time. These capabilities reduce alert fatigue, accelerate incident resolution, and enable predictive operations by identifying issues before they impact users. This evolution from monitoring to observability and now AI-driven observability represents a fundamental shift from reactive system management to intelligent, autonomous operations. Organizations that embrace AI-powered observability gain enhanced visibility, operational efficiency, and the ability to proactively manage increasingly dynamic digital ecosystems, paving the way for the future of self-healing and autonomous IT environments.
Bio
Leader with 18+ years of experience driving large-scale storage and cloud infrastructure initiatives for enterprise platforms. Skilled in end-to-end program execution (requirements, milestones, dependencies, risks, releases) across engineering, product, support, and operations to deliver reliable outcomes.
Deep domain expertise in block storage, enterprise datacentres, and hybrid cloud (AWS, GCP). Partner effectively with engineering and product teams to define success metrics (SLO/SLA), unblock delivery issues, communicate trade-offs to stakeholders, and improve reliability and delivery predictability across multiple concurrent programs.
Sooraj Sanker
MemexAI.Space
When Agents Remember Wrong: Failure Modes in Production Memory
Abstract
AI agents are starting to behave less like stateless chatbots and more like production systems: they call tools, mutate state, personalize behavior, and return to the same user or workflow over time. That creates a new reliability problem. When an agent remembers the wrong thing, the failure is subtle: future behavior changes, the prompt still looks reasonable, and the team may not know which prior read or write caused the issue. This beginner-friendly talk looks at agent memory from an SRE lens. We will walk through common failure modes such as stale memory, accidental overwrites, unbounded personalization, hidden prompt state, missing rollback, and poor auditability. Then we will discuss practical controls: explicit memory tools, scoped user/shared memory, revision history, access logs, safe write boundaries, and simple operational checks. I will use MemexAI, an open-source Postgres-backed memory layer for agents, as the demo system, but the focus is on reliability patterns teams can apply to any agent stack.
Attendees will learn:
- How agent memory can fail in production and why these failures are hard to debug
- A practical checklist for making agent memory inspectable, reversible, and observable
- How to think about agent memory as production state rather than prompt text
Bio
Sooraj Sanker is a Bengaluru-based fullstack and AI engineer, and the founder of MemexAI, an open-source Postgres-backed memory layer for long-horizon AI agents. He spent roughly six years at Hasura and PromptQL, where he worked on conversational analytics, AI agent interfaces, tool-based workflows, artifact-aware chat, and state management for distributed agent execution. His work sits at the intersection of agent infrastructure, context engineering, data UX, and production reliability.
Soham Chakraborty & Bikram Debnath
Sematext & IBM
Choosing the right database: Why ClickHouse has become the standard for storing observability data
Abstract
Observability data is hostile to general-purpose databases. Signals share a common profile: high write throughput, massive cardinality, time-series access patterns, and queries that scan billions of rows expecting sub-second answers. Most databases buckle under this combination. ClickHouse doesn't — but understanding why requires going deeper. In this session, we'll walk through the technical fundamentals that make ClickHouse uniquely suited for observability workloads: columnar storage and vectorised execution, the MergeTree family and TTL-based tiering, sparse indexing for time-range scans, and native ZSTD compression that routinely achieves 10–20× ratios on telemetry data. We will briefly touch the operational aspects of ClickHouse like shard topology and Replication. At the end of the session, the audience will leave with the takeaway of how to build and operate storage backend for modern observability data at scale.
Bio
Soham Chakraborty is a senior devops engineer at Sematext. He has spoken at conferences like Config Management Camp, DevOpsDays, SREDay, KCD among others. He also helps to organize local meetups and events and have previously worked as an organizer of AWS Community Day, Global Azure Kolkata among others
Bikram Debnath is an Advisory Software Engineer at IBM Labs, 3× Patent Holder, and innovator in telemetry and distributed systems. Passionate about Observability, APM, IoT, and Automotive solutions. Skilled in Microservices, Kubernetes, Java, Kafka, and modern data stacks.
Jones Zachariah Noel N
New Relic
Beyond the Hype: Building a Self-Healing Pipeline with Agentic AI
Abstract
Traditional automated remediation (if-this-then-that) is brittle. It fails when faced with the "unknown-unknowns" of distributed systems. When a production incident occurs, the cognitive load on the on-call engineer to parse logs, traces, and metrics is the primary bottleneck for MTTR (Mean Time to Resolution). But with the rise of Agentic AI—LLMs that don't just "chat" but actually execute tools—the dream of a truly self-healing infrastructure is finally within reach. This session moves past the marketing slides to demonstrate how to build an autonomous remediation pipeline that thinks like an SRE. We will explore the architecture of an0 Agentic Observability Loop. Unlike static scripts, an AI Agent can: Observe: Interface with AI Agents to identify the root cause. Reason: Cross-reference telemetry with recent GitHub deployments and runbooks. Act: Execute safe, scoped operations—like rolling back a canary, scaling a K8s deployment, or flushing a cache—using verified toolsets.
Bio
Jones is a seasoned developer turned architect who currently at New Relic being an observability advocate working as Senior Developer Relations Engineer and also focuses on infrastructure and development on cloud platforms like AWS and well into the Serverless ecosystem. Jones is also recognised as AWS Serverless Hero who is enabling the community with latest happenings in the Serverless space with his newsletter, blogs and podcast. Along with this, Jones also regularly shares the best of cloud + observability at multiple global forums and conferences.
Harsha Dixit
Kong
The Invisible Unicode threat in YAML Configuration Files
Abstract
YAML is popular as a language for declarative configurations because of it's readability, support for hierarchical structure, and comments. However, hidden Unicode characters, homoglyphs, and bidirectional text controls can silently alter the behavior of infrastructure definitions, and CI/CD pipelines written in YAML. These invisible characters can evade code review, and even enable attacks that exploit the gap between what developers see and what machines interpret. In this talk, we'll explore real-world examples of rogue Unicode characters in YAML files, understand how they work, and practical defences — from linting, editor configuration and automated detection tools that can prevent these issues from reaching production.
Bio
I build tooling for declarative configuration management, and have previously built tools for API testing and Monitoring.
Sudarshan Balakrishna
Epsilon
The On-Call Apprentice
Abstract
Most engineers dream of writing code - but who keeps the code alive at 3 AM, making sure a million users never see a 500 error? That's the SRE, and the world can't hire them fast enough. This talk is a field-tested roadmap into Site Reliability and Platform Engineering, drawn from two decades of building SRE teams from scratch across multiple organizations.
We'll cover the two real paths in: the fresh graduate's 18-month journey from Linux fundamentals to first on-call rotation, and the career switcher's harder challenge - the mindset shift from "code is done when it compiles" to "code is done when it's observable in production." Attendees will walk away with the seven-pillar SRE competency matrix used in real hiring, the certifications that actually move the needle (and the ones that don't), and the interview signals that separate a true reliability engineer from a résumé.
Backed by data - 73% of high-performing orgs now run formalized SRE practices (DORA/Gartner), 25% YoY job growth, and Amazon losing ~$220K per minute of downtime - this session reframes SRE as the role of the decade. You'll leave with a concrete Week 1 starter pack to launch your own SRE origin story before you get home.
Bio
Sudarshan Balakrishna is VP of IT Operations at Epsilon India, with 20+ years building and scaling reliability engineering teams from the ground up. He leads multi-cloud operations, AIOps platform development, and SRE maturity initiatives, and is an active writer and thought leader on SRE, incident response, and operational excellence. He's passionate about turning production chaos into structured, observable, resilient systems — and about mentoring the next generation of on-call apprentices.
Vishal Alhat
AWS
AI Agents: The Next Evolution in DevOps and SRE Workflows
Abstract
Site Reliability Engineering and DevOps teams are drowning in alerts, incidents, and repetitive tasks. What if AI agents could be your intelligent teammates, not just another tool in your stack? This talk explores the practical integration of AI agents into SRE and DevOps workflows, moving beyond hype to real-world implementation patterns. We'll examine how autonomous agents can transform incident response, automate runbook execution, and provide intelligent context during outages—all while maintaining the reliability standards SREs demand. Through live demonstrations and battle-tested patterns, you'll learn how to architect agent-based systems that integrate with your existing observability stack, handle multi-step troubleshooting workflows, and make decisions under pressure. We'll also explore AI DevOps Agent capabilities and how it helps teams reduce MTTR, automate toil, and scale operational excellence. Whether you're managing Kubernetes clusters, distributed systems, or cloud infrastructure, you'll leave with actionable strategies to augment your team with AI agents that actually work.
Bio
Vishal is a Developer Advocate specializing in DevOps, MLOps, Cloud Security, and Generative AI. He helps developers build secure and responsible AI applications while scaling AI-driven innovation with zero-trust approaches. Vishal conducts hands-on workshops across the APJC region, mentors AWS community members, and speaks at major conferences on DevSecOps, MLOps, and secure GenAI application development. He's passionate about making complex technologies accessible and practical for engineering teams.
Vivek Anandaraman
Cloudelu Labs
Moving from Telemetry Signal Correlation to Graph-Driven AI based RCA
Abstract
Modern production environments span Kubernetes, VMs, serverless, and event-driven systems, yet incident response still relies on manually stitching together dashboards, traces, and logs. While OpenTelemetry improves signal collection, it does not provide a consistent way to model dependencies across services, infrastructure, and asynchronous components. As a result, SREs spend valuable time correlating signals instead of identifying the root cause. This talk presents a graph-driven RCA approach built on a normalized observability layer that converts telemetry into relationships between services, infrastructure, and runtime events. Instead of treating traces, logs, and metrics independently, we derive a dependency graph enriched with time-based observations and health signals. This allows failures to be analyzed as propagation paths across systems rather than isolated alerts. We apply this approach to real-world scenarios across Kubernetes microservices, VM-based workloads, hybrid cloud environments, serverless platforms, and asynchronous systems such as Kafka. The graph highlights cascading failures, dependency latency, and hidden bottlenecks that are difficult to detect using traditional dashboards. We compare this workflow with trace-centric and metrics-first investigations, focusing on time-to-root-cause and operational effort during incidents. Attendees will learn how to build telemetry normalization layers, derive dependency graphs from observability data, and use graph-based reasoning to accelerate incident response. The session focuses on practical SRE workflows, design tradeoffs, and lessons learned from applying graph-driven RCA in distributed systems.
Bio
Founder of from-dev-to-ops Chennai based devops Community. Help Engineering teams implement Observability and Reliability Solutions.
Vignesh Kumar S
GuhaTek
Turn It Off Without Breaking It: Safe Orchestration of AWS Environments
Abstract
Pre-production environments are often left running 24/7, leading to significant cloud waste—but safely automating their shutdown is more complex than it seems. Naive scheduling approaches can easily break dependencies, introduce inconsistent states, or make recovery unreliable. In this talk, I’ll present a real-world implementation of a scheduled, event-driven orchestration system on AWS that safely scales down and restores an entire pre-production environment. The solution uses EventBridge, Step Functions, and Lambda to coordinate state transitions across EC2, RDS, EBS, and application services. A key focus of this system is safe, state-aware execution. Each operation validates the current resource state before acting, ensuring that actions are effectively idempotent and safe to re-run. The workflow enforces dependency-aware sequencing and uses check/wait patterns to avoid acting on transitional or stale states, reducing the risk of unsafe shutdowns and restarts. Rather than relying on blind automation, this approach treats infrastructure changes as explicit, observable workflows, where failures are surfaced clearly and recovery paths are controlled. I’ll also share lessons learned around handling partial executions, the limitations of manual retry strategies, and why idempotency must be considered beyond individual steps. This session will provide practical insights into building reliable, cost-efficient infrastructure automation, along with design patterns that can be applied to any AWS-based environment.
Bio
I am a Site Reliability Engineer with experience in AWS and cloud-native environments, focusing on platform engineering and infrastructure automation. I have worked extensively with containerized systems using Docker and Kubernetes, along with building and operating CI/CD pipelines, and maintaining infrastructure using Terraform. My work centers on operating and improving existing systems, building reliable infrastructure, enhancing automation workflows, and handling real-world failure scenarios in distributed environments.
Neel Shah
StackGen
AIOps Day-to-Day: When AI Fixes Faster Than Humans (and When It Doesn't)
Abstract
In 2026, AIops transforms SRE through 4 maturity stages—alert triage, automated remediation, predictive scaling, self-healing; mapped directly to production ops handling millions of events daily. Custom LLM runbooks crush vendor tools on repetitive toil (Kafka rebalance: 4h→17m MTTR, $0.02/incident, 96% accuracy) but fail spectacularly on complex scenarios (hallucinated kubectl during GPU OOM cascade → 3h outage). OpenTelemetry+LLM pipelines cut alert fatigue 68% but introduced embedding drift surprises. Drawing from 18 months production war stories: LLM etcd recovery runbooks delivered exact curl commands; tool constraints + chaos replay fixed hallucination failures; team velocity dipped 25% during reskilling then recovered +40%. Attendees get copy-paste RAG YAML templates, whitelisted command constraints, drift detection checklists (PSI>0.25), and 6-week LLMOps bootcamp roadmap—targeting >80% automation on top-5 incidents only.
Bio
Neel helps platform engineers and DevOps teams understand and adopt cloud-native infrastructure through talks, demos, and community building. I organise the CNCF Gandhinagar, HashiCorp UG Gandhinagar, and Google Cloud Gandhinagar communities, and I have spoken at 40+ events, including KubeCon India, PlatformCon, HashiTalks, OpenSearchCon Korea, FOSS ASIA, and LinuxFest Northwest. My core focus areas are Kubernetes, GitOps, IaC with Terraform/Vault, AI-powered DevOps tooling, and observability pipelines. I've mentored 15+ hackathons and open-source programmes. Certifications: GCP DevOps Professional, Azure AZ-104, FinOps Certified Engineer, Terraform Associate, Vault Associate.
Jatin Mehrotra
AWS
From Alert to Auto-Fix: Open-Source AI Agents That Heal Your Kubernetes Cluster
Abstract
In 2026, we're moving from Automated Ops to Agentic Ops — systems that reason, investigate, and remediate without human intervention.
In this demo-heavy session, I'll build a self-healing Kubernetes cluster live using CNCF projects — K8sGPT (auto-fixes cluster issues), HolmesGPT (investigates complex failures), and Kyverno (guardrails that control what the AI can touch). You'll watch an OOMKilled pod get auto-patched, a policy block the AI from touching critical workloads, and a cascading failure diagnosed with a full RCA delivered to your team's communication channel. You'll leave knowing what to automate, what to gate, and what to leave to humans.
Bio
I am a developer advocate at AWS. I focus on building cloud infrastructure based solutions and now focusing on Generative AI solutions while prioritising a developer-centric approach to my work. Outside of work, I enjoys lifting, Hiking and Saunas.
Shobhit Gupta
Segwise.ai
What We Learned Running AI Agents in Production at Segwise AI
Abstract
Over the past year, we've been building and operating AI agents that help marketers analyze campaign performance and investigate why metrics change. While the demos looked impressive, production quickly exposed a different set of challenges: agents choosing the wrong tools, making unsupported assumptions, becoming expensive to run, and failing in ways traditional monitoring doesn't catch.
This talk will be a look at what worked, what didn't, and what surprised us while running AI agents in production.
Bio
Shobhit Gupta is co-founder of Segwise AI, where he works on AI-powered analytics and agent systems. Previously, he worked at WhatsApp, Uber, Yahoo, and FamPay as a backend engineer or engineering manager. He enjoys building products that help people make sense of complex data.
Thejaswi Mudda
Qualcomm
KPIx Framework for Modern SRE and Engineering Organizations
Abstract
This session will focus on how engineering organizations can design meaningful, actionable KPIs that improve reliability, operational excellence, and business outcomes.
Key discussion areas include:
Why most KPIs fail
Critical Success Factors (CSFs) and KPI alignment
SRE and operational KPIs
KPI anti-patterns and metric overload
Governance and ownership models
Practical lesson from enterprise-scale implementations
The session will be practical, experience-driven, and focused on applying KPIx framework methodology effectively in modern engineering and SRE environments.
Bio
The story of Thejaswi Mudda (Theju), is one of transformation – where a relentless pursuit of clarity turned raw data into strategic direction. With over two decades of experience across SRE, Agile transformation, DevOps, quality systems, and performance measurement, Theju has operated at the intersection of technology, systems thinking, and human behavior. From piloting agile practices at IBM to leading enterprise-wide KPI and OKR rollouts at Qualcomm, one insight has shaped his journey: “Real breakthroughs rarely come from just better tools - but from asking better questions about performance.” As a SRE Manager at Qualcomm, Theju didn’t just coach teams on frameworks – he engineered performance systems. These systems connected day-to-day delivery with strategic purpose, embedding clarity and accountability into the DNA of operations. Across his global work with organizations like Chase Manhattan Bank, State Street Financial, Instinet Corp., and IBM clients, one challenge became impossible to ignore: Performance Management Engineering is rarely addressed in academia, despite its critical role in organizational success. Too often, the responsibility for defining performance metrics is handed to managers or engineers who, while highly skilled in their domains, have limited grounding in performance management principles and KPI design. This gap not only limits the effectiveness of metrics but also misses opportunities to link measurement directly to strategy. This realization birthed the KPIx Framework – a methodology grounded in real-world practice, enabling organizations to define KPIs that go beyond tracking – to drive execution, alignment, and strategic agility. “Dashboards don’t deliver results. People do. The right KPIs simply guide them with clarity and confidence.” Mission in Motion Theju now partners with CIOs and transformation leaders to create performance systems that don’t just report metrics – but activate them. Theju’s mission is bold and clear: To help organizations translate strategy into KPIs that are scalable, data-integrated, and human-centric – empowering teams to align, prioritize, and perform with precision. A Vision for the Future At the heart of this journey lies a powerful belief: KPIs should inspire – not intimidate. Theju envisions a future where: • Every organization has the confidence to define what truly matters • AI and human insight combine to create intelligent, adaptive KPI systems • KPIs don’t just reflect performance – they mobilize it That future has begun - with KPIx Framework.
G Saikrishna
CitiusTech
From Reactive Operations to Autonomous Reliability: Building an AI-Powered SRE Platform
Abstract
Modern engineering teams rely on multiple tools for monitoring, incident management, security, compliance, and cloud operations. This session explores how AI can help SRE and Platform Engineering teams move from reactive troubleshooting to proactive and autonomous operations. Using a real-world platform engineering case study, I will demonstrate how observability, security insights, compliance checks, and automated remediation can be unified into a single operational workflow. Attendees will gain practical insights into reducing alert fatigue, improving incident response, enhancing reliability, and implementing AI-assisted operations in cloud-native environments.
Bio
A DevSecOps and Site Reliability Engineer with 5+ years of experience in cloud platforms, automation, Kubernetes, CI/CD, Infrastructure as Code, and cloud security. Passionate about Platform Engineering and AI-driven operations, I build secure, scalable, and reliable cloud-native systems.
Pratik Mahalle
DrDroid
Debugging Knowledge Is Infrastructure Too
Abstract
Every team has an engineer who makes on-call look easy. They know the service that quietly degrades every Monday morning, the log pattern that precedes a cascade, and which alert has been firing incorrectly since the 2023 migration. When they leave, MTTR doubles and not because anything broke, but because the knowledge that made fast debugging possible was never captured. This talk is about making incident expertise durable. We cover how to extract the decision patterns that live in senior engineers' heads, encode them into investigation workflows that surface automatically during incidents, and measure whether the transfer is working. We walk through what worked, what created new toil (the "automated runbook" trap), and one incident where the system suggested the wrong root cause and why that was still a net win and more
Bio
Pratik has been in the observability space for more than a year now. With a background spanning SRE and platform engineering, he focuses on OpenTelemetry in production, Kubernetes fleet operations. He is an active open source contributor and member at Opentelemetry.
Saurabh Hirani
One2N
Observability Maturity Model for AI Applications
Abstract
While working with our customers, we are seeing that teams are shipping AI features fast but skipping the instrumentation that tells them what's actually happening in production.
AI applications fail differently from traditional services. Token exhaustion, retrieval quality drift, and provider outages don't show up in HTTP status codes. But how much instrumentation do you actually need, and when does the effort stop paying off?
To distill what we've learned from instrumenting customer AI applications, we built a reference RAG app and applied four levels of instrumentation: zero-code auto instrumentation, manual OTel spans, AI-native telemetry libraries, and an external AI gateway. Each level adds visibility but also adds effort, from zero lines of code to a production grade telemetry pipeline setup.
This talk presents a practical maturity model. For each level, we show: what you can now see, what failure modes you can catch, what's still invisible, and what it costs in engineering time. We use real traces and dashboards from a running system to ground the comparison.
Along the way, we bust some practical myths: why standard percentile calculations silently produce garbage for RAG similarity scores, and why "cheaper" models can end up costlier than premium ones in specific situations.
Whether you're deciding where to start or evaluating whether the next level of investment is worth it, you'll leave with a clear framework mapping effort to observability payoff, and a working open-source repo to validate it yourself.
Bio
Saurabh Hirani is a Principal SRE at One2N with 20+ years of experience in infrastructure, operations, and reliability engineering. He has worked with startups and enterprises to build production-grade monitoring systems with a focus on automation and minimalism.
Previously, he led customer success teams for observability products and architected resilient telemetry ingestion pipelines for JioHotstar during major IPL events. Currently, he works with customers to instrument and observe their AI applications in production.
Priyank Upadhyay
RubixKube
The SRE Fear Paradox: Why AI Scares Operators More Than Outages
Abstract
Developers got disrupted by AI. They shrugged. SREs are next. They're terrified. The difference: a Copilot mistake is reverted in seconds. An autonomous AI system making remediation decisions in production is irreversible. One breaks a function. The other breaks trust in your infrastructure. But the real fear runs deeper. SREs have spent years building muscle memory around their systems—understanding failure modes, owning the reliability narrative. AI tooling promises to abstract that away. Use our platform. Upload your metrics. Trust our models. Your data lives in our cloud. Let us handle it. That's not autonomy. That's surrender. This talk cuts through the noise. We'll walk through why SRE fear of AI is rational, not paranoid. Why the current wave of 'AI SRE tools' are built for vendors, not operators. And why regulation (GDPR, data residency, compliance) is actually the key to building AI systems that SREs will adopt. The move: AI that lives where your systems live. On your infrastructure. Your data stays yours. Full transparency into every decision. Gradual autonomy—from suggest to execute-with-approval to autonomous. Built for regulated industries from day one. When privacy and control are baked in, AI stops being something that happens to you and becomes something you build. That's when SREs stop being scared and start being dangerous.
Bio
Co-Founder & CEO of RubixKube. Building autonomous operating systems for production. CNCF member, Kubernetes maintainer. Spent years watching SREs get buried under tooling and constraint. Now building the opposite: one intelligent operating layer that learns systems permanently instead of asking humans to remember. Previously at yellow.ai and Avesha. Go. Causal graphs. Agents that don't hallucinate in production.
Nandini Bhatt
Xurrent
KeynoteO11y: The math you miss
Abstract
We're drowning in data but starving for insight. At peak load, we were collecting thousands of metrics per second, yet we still missed the signals that mattered. Worse, the observability overhead itself was creating garbage-collector pressure that degraded the systems we were trying to understand. The lesson we learned the hard way: observability isn't about collecting more data—it's about understanding the math behind the data and choosing the few signals that actually predict failure.
Bio
Nandini Bhatt is a Site Reliability Engineer II at Xurrent with a background in DevOps, SRE, and cloud infrastructure. She has previously worked at Xurrent, PhysicsWallah, and EY, building experience across platform operations, automation, and reliability engineering. A strong advocate for open source and community-driven learning, Nandini is passionate about improving system reliability, observability, and operational excellence while actively contributing to the DevOps and SRE community.
Uma Mukkara
Harness
KeynoteWhy Is Resilience Testing Non-Negotiable in an Enterprise SDLC?
Abstract
In this Keynote, Uma Mukkara, Head of Harness Resilience Testing and Co-Creator of LitmusChaos, explains why resilience must be built and tested throughout the Software Development Life Cycle, not treated as something to address after production issues occur.
He defines resilience as the ability of business services to withstand system failures, high load, and disasters, and shows how reduced resilience increases operational and business risk. The keynote introduces AI-powered resilience testing to help teams quantify risk, identify weaknesses early, and continuously measure, mitigate, and improve reliability across SDLC phases.
By combining chaos testing, load testing, and disaster recovery testing into a unified resilience strategy, Uma emphasizes that resilience is not optional. It must be proactively validated as a core practice of modern software delivery.
Bio
Uma Mukkara is Head of Resilience Testing at Harness and founder of ChaosNative. He is a recognized leader in chaos engineering, resilience testing, and cloud native reliability, with deep experience building products and teams across infrastructure and DevOps. Uma is passionate about helping organizations improve system reliability through modern resilience engineering practices.
Siva Bagavathi & Balaji Venkatesan
GuhaTek
KeynoteWhat Breaks First When Scaling to 30 Million Users?
Abstract
Everyone talks about scaling systems to millions of users. Few talk about what actually breaks first.
As organizations grow, the first bottlenecks rarely appear where expected. Databases run out of connections before they run out of CPU. Message queues quietly become storage systems. Observability platforms generate more data than the applications they monitor. Infrastructure scales, but operations struggle to keep pace.
In this session, we present a Reliability Scaling Framework based on real-world experiences navigating the journey from one million to thirty million users. Through practical examples and lessons learned, we explore how teams can identify and eliminate reliability bottlenecks across applications, data platforms, messaging systems, Kubernetes, observability, and operational workflows.
Beyond technology, we discuss why successful scaling requires organizational coordination and why the modern SRE must act as the captain of reliability—aligning engineers, architects, product teams, and executives toward a common goal while balancing availability, performance, and cost.
Attendees will gain a repeatable framework for assessing scalability readiness, preventing common reliability pitfalls, and building systems—and organizations—that can confidently support the next order of magnitude in growth.
Bio
Seasoned, forward-looking professionals with around two decades of experience in Site Reliability Engineering, Solution architecting, Performance engineering, Capacity planning, Chaos Engineering, product development, automation and setup SRE for large enterprise applications in various business domains. Consistently recognized as competent individual, skilled at coordinating with cross-functional teams in a fast-paced environment to steer timely completion of project with budgetary constraints.