SREday

Site Reliability, DevOps and Cloud

May 21, 2026 MaibornWolff

1
Day
10+
Speakers
2
Tracks
120+
Attendees

SREday is a worldwide series of community events for engineers who build, ship and run modern software systems. Across cities around the world, we bring together people working in reliability, cloud, DevOps, observability and production engineering to share real-world experience, connect with their local community and explore how these disciplines are evolving in the age of AI.

Companies presenting:

Altinity, AWS, CloudAstro, cloudiamo.com, enmacc, ewake, Google, Hyground, ilert, Imply, MaibornWolff GmbH, MeloMar IT, PromLabs, Siemens, Tipico Technology Services GmbH, Trimble, Varnish Software, x-cellent technologies GmbH
Topics so far:

This is a past event, what's next?

Schedule

May 21, 2026 2 parallel tracks 9AM - 7PM Munich, in-person
view as table
7th Floor • Track 1

09:00

_Michael Harrer & Mark Pawlikowski

09:30

Benjamin Hofmann

KeynoteHow an AI SRE agent can manage 20,000 workloads

Hyground
IT systems are not neat self-contained boxes with a few components. A single application deployment today has hundreds of moving parts. An IT landscape contains thousands of those applications. On the other side sit AI agents with vast world knowledge. Like humans they struggle with context overload. They can't possibly keep a whole datacenter in their head at once. Neither can we. We navigate. In this talk we'll show how an agent can navigate and operate a system of hundreds of thousands of components, working from a live map of the infrastructure and a connector layer that lets it act on anything the map reveals. The result: an agent that adapts itself to the landscape it walks into, instead of a bespoke setup for every shape of IT.... Read more

10:00

Michael Harrer

KeynoteDigital Sovereignty Beyond Security: What Platform Teams Need to Decide Now

MaibornWolff GmbH
Digital sovereignty goes far beyond data protection and IT security. Europe’s digital future currently depends on a small number of global tech providers, bringing risks such as vendor lock-in and geopolitical exposure. For platform engineering teams, these concerns quickly become practical decisions. Which workloads can run on which platforms? Which dependencies are acceptable? And how meaningful is sovereignty once you move past marketing claims? This talk examines what digital sovereignty means in real-world platform engineering. It covers the key challenges, the trade-offs teams must navigate, and how organizations can build viable strategies. Drawing on hands-on project experience, it outlines pragmatic approaches to balancing technological capability with independence and compliance.... Read more

11:00

Kyle Hoondert

KeynoteDecoupling Observability for Incident Response at Scale

Imply
On-call incidents don’t fail because teams lack dashboards. They fail because observability systems slow down under real investigative load As telemetry volumes grow and retention windows expand, SRE teams are being asked to run deeper, broader investigations—often under time pressure—on platforms that were designed for steady-state monitoring, not bursty incident response. Tightly coupled observability stacks bind storage, compute, and query together, forcing teams to overprovision infrastructure, limit retention, or accept degraded performance during incidents. In this talk, we’ll explore why decoupling observability architectures is becoming essential for SRE teams operating at scale. Using a real incident investigation workflow, we’ll break down how separating data storage, compute, and interaction layers allows teams to keep fast, reliable monitoring while elastically scaling investigations when incidents occur.... Read more

11:30

Birol Yildiz

KeynoteWhen Incidents Fix Themselves: AI SRE in action

ilert
The next evolution of incident response isn’t faster alerts, it’s autonomous resolution. Join ilert CEO Birol Yildiz as he shows how AI SRE agents now diagnose and remediate outages without waking anyone up. Learn how these systems combine observability data, deployment context, and code intelligence to restore services in minutes and hand over clean incident reports instead of 3 a.m. pages.... Read more

12:00

Lunch & networking

11th Floor

13:00

Laysa Uchoa

The LLM Said What?! A Survival Guide

enmacc
LLMs are confident liars. We will start with a true story about an internet meme, and an AI that learned exactly the wrong lesson, and use it to explain why hallucinations happen and how to stop them This talk walks through a production-ready approach to grounding LLMs in real data using Retrieval-Augmented Generation on OpenSearch. We will compare RAG against fine-tuning and explain why retrieval wins for fact-based use cases. We will dig into hybrid search, combining BM25 lexical scoring with k-NN vector search, and show how to tune the normalization and weighting that ties them together. We'll spend real time on chunking strategies because chunking is where most RAG projects quietly fail. Finally, we will introduce a three-layer evaluation framework covering retrieval quality, configuration, and answer faithfulness. You will leave with the mental model that turns RAG from guesswork into engineering.... Read more

13:30

Poone Mokari

Production is a wilderness. Treat it like one.

ewake
Production is a wilderness. The terrain shifts every minute, meaning human and agent failures are not caused by missing intelligence. They come from acting on stale context. Discovery takes time, and in production it is often the most expensive part of the workflow. In this talk, I show why AI SRE agents fail when they rely on runtime discovery, and what changes when they operate on live context instead of snapshots. The short version: an AI SRE that admits uncertainty is the only kind you can safely let run.... Read more

14:00

Stefan Lenz & Michele Dodic

Designing Your Custom-Fit Observability Launch

Siemens
More and more organizations are realizing that observability is the missing piece in how they deliver and operate digital products: teams get pulled into firefighting, troubleshooting stays siloed, and leaders lack a clear line from system behavior to business outcomes. In this talk, we share first-hand experience designing an organization-wide observability rollout in a complex environment—guided by SRE principles and treating reliability as a product. Rather than starting with a mass, technology-first onboarding, we start from business objectives and a clear value proposition. These are then translated into clear requirements, which are used to select an observability platform that matches your custom need, scale, and constraints. We then show how to define the right level of onboarding based on your product portfolio, and how to align early with product and delivery stakeholders so expectations, ownership, and priorities are clear from day one. You’ll learn a practical approach to structuring service onboarding across business, application, and infrastructure layers to achieve end-to-end visibility and correlation across services and domains—where the most valuable insights emerge. Finally, we cover how to enable engineering teams early and set up an operating model with shared goals, shared responsibility, and dedicated roles to drive adoption at scale. Our goal is to provide attendees a repeatable blueprint to design an observability launch that fits their organization.... Read more

14:30

Josh Lee

OpenTelemetry: Playtime Is Over

Altinity
So you finally got your organization to invest in OpenTelemetry. You carefully evaluated observability backends and picked the perfect one. Everything is awesome. Then twelve months later, your costs have skyrocketed and you can’t explain why. What happened? This talk examines how to emit meaningful telemetry while keeping costs under control, by exploring the following: - What to actually instrument - Which metrics to focus on - Pipeline efficiency with OTel Arrow Applying sampling, filtering, and intentional instrumentation to cut down on noise Schema management and validation with tools like Weaver We’ll review the ingredients of a mature observability implementation with OpenTelemetry: one that grows with you instead of overwhelming you. You’ll learn how to apply cost-effective techniques to achieve meaningful observability. Speaker Notes (visible to organizers only) As more organizations embrace OpenTelemetry and mature their Observability practice, we find ourselves coming out of that Observability and OpenTelemetry "honeymoon period". We've gone from, “We’re using OpenTelemetry, therefore we have Observability” to "How do we actually make this work for us?" This talk will equip organizations to build a sustainable and long-lasting observability practice built on OpenTelemetry.... Read more

15:00

Networking and Sponsor Crawl

11th Floor

15:30

Chiara Dellantonio

Agents in Action: How Google is Automating Operational Toil

Google
Imagine an Oncall shift where you don’t start your day sifting through routine capacity alerts, nudging stuck rollouts, or closing noisy, low-impact tickets. Instead, you get to tackle things that matter. This is the goal we’re chasing at Google. We are developing a system where software agents can autonomously handle a significant chunk of operational toil. The key is to do this generically and horizontally, making the solutions broadly applicable crossing the lines between developers and operations. In this session, I’ll share our journey and lessons learned. We’ll cover the significant challenges, including evaluation, ensuring safe and secure operations, and how to codify complex, sometimes opinionated, remediation steps. I’ll outline the infrastructure we’ve put in place due to those challenges and requirements. This talk aims to provide a practical perspective on leveraging automation and agents in a production environment. You’ll leave with critical questions to consider for your own agent that interacts with production.... Read more

16:00

Renato Losio

Five Hard Lessons from Five Years of So-Called Serverless Databases

cloudiamo.com
After five years of managing serverless databases, I have learned that my rollercoaster journey is very similar to the CPU usage you dream of seeing in the console. This session shares five hard-earned lessons learned while working with so-called serverless databases.... Read more

16:30

Andrea Valenti

The Worst Week on My Team Is the Most Important One

Trimble
Every week, one engineer on my SRE team takes the gatekeeping shift. They handle everything that arrives — every interrupt, every ad-hoc request, every ticket without context or priority. Everyone else gets to think. It is, as we still say internally, a horrible week. Triage under pressure is not a new idea. Emergency rooms do it. ITIL codified it. Kanban made it visual. The principle is the same: not everything that arrives is equal, and treating it as equal is how teams drown. We did the same thing for SRE. We got very good at it. That was the first problem. By the time the gatekeeper role was mature, it was fast, accurate, and resolving things in hours that used to take days. And then we stepped back and looked at what it was resolving. A significant portion of the work flowing through that seat shouldn't have been fixed by SRE at all. It should have been automated. Or it should have been rejected as a requirements problem — something that needed to be addressed upstream, not patched downstream on a weekly basis. We had built a perfect team for doing the wrong things quickly. The role shifted. Not triage-and-resolve. Triage-and-surface. The gatekeeper's job became identifying where the real problem lived — automation candidate, requirements gap, architecture debt — and routing accordingly rather than absorbing it. TOIL peaked at 83.9% in 2023 during three simultaneous acquisitions. By 2025 it was 44.7%, inside Google SRE's benchmark. The gatekeeping rotation was the practice that moved that number — not by going faster, but by going to the right place. Rotating who sits there is what stops it becoming one person's problem. Engineers who've done the horrible week know exactly which ticket types need to stop existing. Practices cross-pollinate. Stakeholders get exposed to different people asking different questions. The P&L context shifts as ownership spreads. In 30 minutes: how we implemented it, how we almost ruined it by optimizing the wrong thing, and what the data looked like when we corrected course. You can start this next sprint. No budget, no organizational permission required — just one week, one person, and the willingness to ask why it keeps coming back.... Read more

17:30

Happy Hour until 8PM

11th Floor

19:00

Wrap up

Scan each other's QR codes & head to a nearby pub!
11th Floor • Track 2

12:00

Lunch & networking

11th Floor

13:00

Boris Zaikin

Building a Human-in-the-Loop AI Dev Team for Safe Code Changes

CloudAstro
AI can already help write and test code, but many teams still do not want fully automatic changes. In this talk, I will show a simple Human-in-the-Loop Agentic SDLC setup where AI agents can plan work, update code, and run tests, but important actions still need human approval. I will show the MVP demo and also compare a few free alternatives for the coding layer, including Cline, Continue, and OpenHands.... Read more

13:30

Julius Volz

Why I Recommend Native Prometheus Instrumentation over OpenTelemetry

PromLabs
With all the hype around OpenTelemetry, you may be tempted to use OpenTelemetry and its SDKs for all of your application instrumentation needs. However, when it comes to generating metrics for usage in Prometheus, you should at least think twice before going all in on OTel. Not only do you risk throwing away some of the core features that define Prometheus as a monitoring system, but you'll also end up with awkward metrics translation and escaping issues, as well as other inefficiencies and complexities. That's why I still recommend using Prometheus's own native instrumentation client libraries over the OTel SDKs if you want to get the best possible Prometheus monitoring experience. In this talk, I'm going to lay out some of the major reasons that led me to this opinion.... Read more

14:00

Arnaud Jean

Create Your Own Role-Playing Game with Agentic AI using Strands Agents

AWS
Come discover how to code a Game Master that will orchestrate multiple AI agents, each specialized in a particular task. We'll explore concepts like agent tools, the MCP (Model Context Protocol), A2A (Agent to Agent), and RAG (Retrieval-augmented generation) to create agents and/or MCP servers that roll dice, verify DnD rules, and generate the story as it unfolds. Whether you're a role-playing game fan or not, there will be things to learn during this workshop :)... Read more

14:30

Dmytro Patserkovskyi

Design Smarter Grafana Dashboards: A Few Simple Principles That Work

Tipico Technology Services GmbH
Grafana dashboards are often built when we don’t have time to build them and used during incidents, when we don’t have time to understand them. In this talk, we’ll dive into real-world examples and explore multiple levels of monitoring through screenshots and stories from the field. By the end of the session, you’ll walk away with a few simple yet powerful principles to design and organize Grafana dashboards that truly help during critical moments.... Read more

15:00

Networking and Sponsor Crawl

11th Floor

15:30

Vasil Kulakov

One Bot, One Pod, One Problem at a Time

Team Lead, SRE
Running a Telegram bot as a single pod is easy. Scaling it to multiple replicas is where things get interesting. This talk follows the real evolution of a production bot for a language-learning platform. Each step was driven by a concrete problem: polling breaks when two instances race for the same update, so you switch to webhooks and introduce an ingress. In-memory sessions disappear between replicas, so Redis shows up. Reminder workers block the webhook handler, so they become separate binaries running as CronJobs. You add a second language pair and suddenly the same Helm chart needs to deploy two isolated bots — and a subtle bug surfaces where one bot answers for the other. We'll also cover how LLM calls made cost invisible (and how a small in-cluster usage-tracking service fixed that), plus encrypted secrets in git with SOPS across a multi-chart monorepo.... Read more

16:00

Simon Mayer

From Bare Metal to Kubernetes: Building a Cloud You Actually Own

x-cellent technologies GmbH
Public cloud providers offer convenience — but at the cost of control, transparency, and increasingly, budget. What if you could have the same self-service Kubernetes experience, on your own hardware, built entirely on open source technology? This talk walks through the full stack of building your own cloud platform to offer Kubernetes — layer by layer. We start at the bottom with Networking and Compute. From there, we move up to Metal-as-a-Service with [metal-stack.io](http://metal-stack.io/), which turns bare-metal servers into programmable, API-driven cloud infrastructure — with on-demand provisioning, physical tenant isolation, and no hypervisor overhead. On top of that, we explore how Gardener and ClusterAPI handle Kubernetes cluster orchestration at scale: self-service cluster provisioning, automated lifecycle management — delivering the public cloud feeling, without the public cloud dependency. We will also touch on what owning the complete stack means for SRE teams: from observability across every layer, to the ability to see exactly what happens during debugging — because there are no black boxes, only open source code you can read, trace, and understand.... Read more

16:30

Marcel Koert

It's not the tools it is us

MeloMar IT
Reliability fails in surprising ways—not because engineers don’t care, but because our brains are optimized for speed, not accuracy. In high-pressure IT environments, that leads to familiar patterns: premature conclusions during incidents, “obvious” fixes that don’t fix anything, risky changes that felt safe at the time, and meetings where everyone nods while the real problem stays untouched. This lecture is a sharp, highly relatable look at the human side of reliability: how bias shapes decisions in operations, why smart teams repeat the same mistakes, and what lightweight practices help you improve outcomes without adding bureaucracy. Expect real-world scenarios, humor, and practical takeaways you can apply immediately—without me giving away the full playbook.... Read more

17:00

Thijs Feryn

Caching Kubernetes? Introducing the Varnish Gateway Controller for Kubernetes

Varnish Software
Now that the Nginx Ingress Controller for Kubernetes is deprecated, a lot of organizations are re-evaluating how they are going to expose Kubernetes services to the outside world. Gateway API is the obvious successor of Ingress and in this presentation Thijs will introduce the brand new Varnish Gateway Controller for Kubernetes. Varnish is a well-known reverse caching proxy that accelerates any type of HTTP workload. The open source project has been around for more than 15 years and is often deployed inside Kubernetes clusters to accelerate individual services. In this presentation Thijs will show how the power of Varnish adds caching to Kubernetes at the Gateway API level, while still supporting all the routing capabilities that a Gateway Controller is known for.... Read more

17:30

Happy Hour until 8PM

11th Floor

19:00

Wrap up

Scan each other's QR codes & head to a nearby pub!
Time 7th Floor 11th Floor
09:00 Conference Introduction
_Michael Harrer & Mark Pawlikowski
09:30 KeynoteHow an AI SRE agent can manage 20,000 workloads
Benjamin Hofmann • Hyground
10:00 KeynoteDigital Sovereignty Beyond Security: What Platform Teams Need to Decide Now
Michael Harrer • MaibornWolff GmbH
10:30 Coffee Break - 7th Floor Only
_Coffee Break_
11:00 KeynoteDecoupling Observability for Incident Response at Scale
Kyle Hoondert • Imply
11:30 KeynoteWhen Incidents Fix Themselves: AI SRE in action
Birol Yildiz • ilert
12:00 Lunch & networking
13:00 The LLM Said What?! A Survival Guide
Laysa Uchoa • enmacc
Building a Human-in-the-Loop AI Dev Team for Safe Code Changes
Boris Zaikin • CloudAstro
13:30 Production is a wilderness. Treat it like one.
Poone Mokari • ewake
Why I Recommend Native Prometheus Instrumentation over OpenTelemetry
Julius Volz • PromLabs
14:00 Designing Your Custom-Fit Observability Launch
Stefan Lenz & Michele Dodic • Siemens
Create Your Own Role-Playing Game with Agentic AI using Strands Agents
Arnaud Jean • AWS
14:30 OpenTelemetry: Playtime Is Over
Josh Lee • Altinity
Design Smarter Grafana Dashboards: A Few Simple Principles That Work
Dmytro Patserkovskyi • Tipico Technology Services GmbH
15:00 Networking and Sponsor Crawl
15:30 Agents in Action: How Google is Automating Operational Toil
Chiara Dellantonio • Google
One Bot, One Pod, One Problem at a Time
Vasil Kulakov • Team Lead, SRE
16:00 Five Hard Lessons from Five Years of So-Called Serverless Databases
Renato Losio • cloudiamo.com
From Bare Metal to Kubernetes: Building a Cloud You Actually Own
Simon Mayer • x-cellent technologies GmbH
16:30 The Worst Week on My Team Is the Most Important One
Andrea Valenti • Trimble
It's not the tools it is us
Marcel Koert • MeloMar IT
17:00 Caching Kubernetes? Introducing the Varnish Gateway Controller for Kubernetes
Thijs Feryn • Varnish Software
17:30 Happy Hour until 8PM
19:00 Wrap up

Speakers

_Coffee Break_
_Michael Harrer
& Mark Pawlikowski
Andrea Valenti
Trimble
Arnaud Jean
AWS
Benjamin Hofmann
Hyground
Birol Yildiz
ilert
Boris Zaikin
CloudAstro
Chiara Dellantonio
Google
Dmytro Patserkovskyi
Tipico Technology Services GmbH
Josh Lee
Altinity
Julius Volz
PromLabs
Kyle Hoondert
Imply
Laysa Uchoa
enmacc
Marcel Koert
MeloMar IT
Michael Harrer
MaibornWolff GmbH
Poone Mokari
ewake
Renato Losio
cloudiamo.com
Simon Mayer
x-cellent technologies GmbH
Stefan Lenz
& Michele Dodic
Siemens
Thijs Feryn
Varnish Software
Vasil Kulakov
Team Lead, SRE

Venue

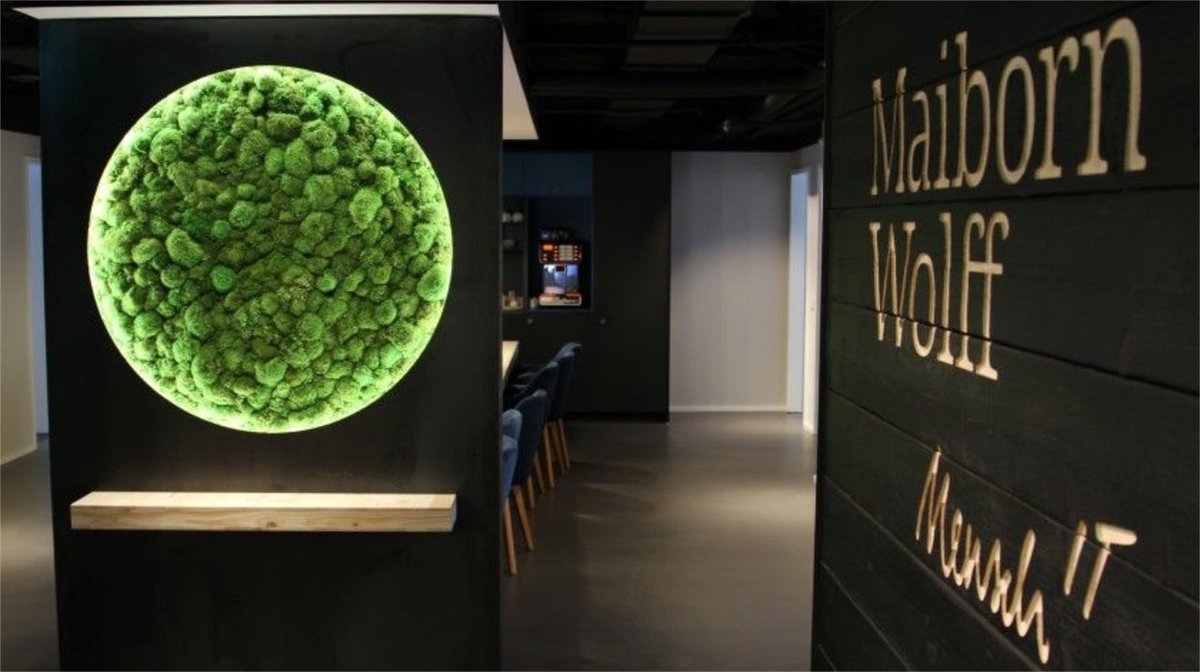
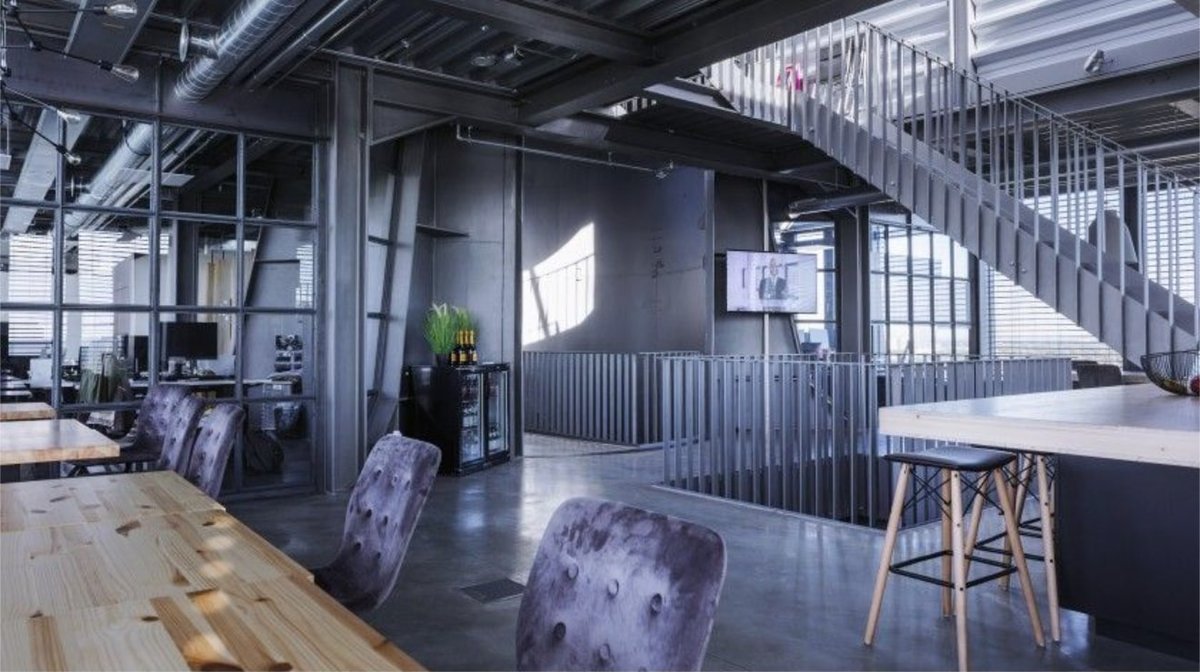
MaibornWolff - office & event space

Drygalski-Allee 25
81477 Munich, Germany

Sponsors & Partners

Want to become a sponsor? Get in touch!
Let's talk!
We'll email you and share prospectuses for relevant events.
We'd like to (one or more)
Pick at least one
Conferences (one or more)
Pick at least one
Regions (one or more)
Pick at least one
Budget
Pick one